
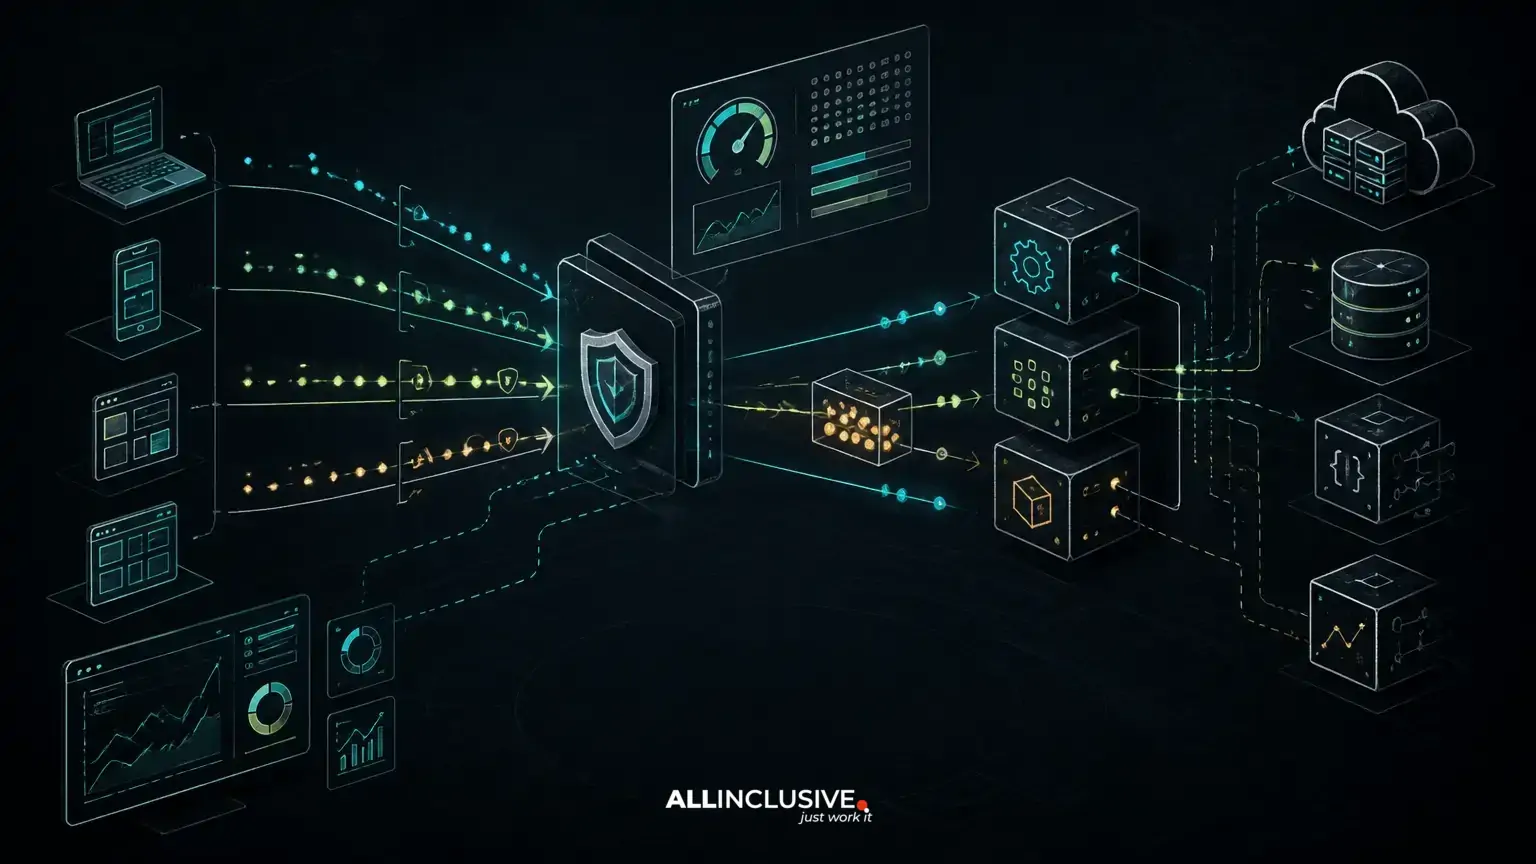
API rate limiting controls how frequently a client can call an interface over a defined period. Done well, it protects application capacity, downstream providers, and shared infrastructure without turning normal customer workflows into intermittent failures. Done poorly, it creates confusing errors, synchronized retries, and support issues that are difficult to diagnose. For teams evaluating api rate limiting, this implementation detail is expanded in custom software development.
The right design is not simply a number of requests per minute. It combines an enforcement algorithm, a meaningful identity model, endpoint-specific policy, clear response headers, client behavior, and operational monitoring. Rate limits should also work with authentication, webhooks, queues, idempotency, and retry policies rather than treating each concern in isolation.
For teams building or extending a custom API, API development should define these behaviors as part of the contract, not as an infrastructure detail added after launch.
Why API rate limiting is a reliability control
Rate limits address several different risks:
- Capacity exhaustion: A busy client, accidental loop, or traffic spike can consume application workers, database connections, or provider quotas.
- Unfair resource allocation: Without per-client controls, one tenant can degrade service for others.
- Abuse and reconnaissance: Limits can reduce the impact of credential misuse, scraping, and repeated expensive requests, although they are not a replacement for authentication or authorization.
- Downstream protection: Your API may call a payment, CRM, ERP, or AI provider with its own quotas and billing constraints.
Rate limiting does not make an endpoint inherently safe. An authenticated client can still send harmful traffic, and a low request count can still trigger expensive database queries. Combine limits with authorization, input validation, payload limits, timeouts, query controls, and observability.
Choose a limiting model that matches the workload
Different algorithms produce different client experiences and operational trade-offs.
Fixed windows
A fixed-window counter allows a defined number of requests during intervals such as one minute or one hour. It is easy to explain and implement, but requests near a window boundary can produce a burst larger than the nominal rate. This may be acceptable for low-risk endpoints, but it can be awkward for expensive operations.
Sliding windows
A sliding-window approach evaluates requests across a continuously moving interval. It smooths boundary behavior and can represent recent usage more accurately, but it generally requires more state or a more sophisticated counter strategy.
Token buckets
A token bucket replenishes capacity at a defined rate and permits short bursts while tokens are available. This often maps well to user interfaces and integration workloads: a client can complete a small burst without being penalized, while sustained traffic remains bounded. The bucket size and refill rate should reflect actual workload requirements rather than arbitrary round numbers.
Concurrency limits
Request-rate limits and concurrency limits solve different problems. A client may send only a modest number of requests per second, but if each request performs a slow export or external lookup, many can remain active simultaneously. Add concurrency controls for long-running or resource-intensive operations, and prefer asynchronous jobs when work does not need to complete during the HTTP request.
Rate-limit the right identity and resource
A global limit is rarely sufficient for a multi-tenant API. Consider several dimensions:
- Tenant or account: Useful for protecting contractual capacity and preventing one organization from affecting another.
- User: Helpful where individual workflows or credentials need separate controls.
- API key or OAuth client: Appropriate when applications have distinct operational profiles. Authentication identifies the caller; it does not automatically determine the quota policy.
- IP address: Useful for anonymous endpoints and broad abuse controls, but unreliable as the sole identity for users behind proxies, NAT, or shared networks.
- Endpoint or operation: A read-only lookup, bulk export, password reset, and write operation may require different limits.
Use a layered policy when necessary. For example, an account may have a sustained organization-wide quota, each client application may have its own allocation, and expensive report generation may have a separate concurrency limit. Document which limit is being exceeded so support teams and integrators can act on the signal.
Separate normal traffic from expensive work
Applying one limit to every route makes policy simple but often produces the wrong incentives. A lightweight metadata request and a bulk synchronization call should not necessarily consume identical capacity.
Classify operations by their resource profile. Read endpoints that hit indexed data may tolerate higher sustained rates than endpoints that perform joins, call third-party services, or generate files. Bulk operations should often be asynchronous: accept the request, create a job, process it through a queue, and expose status or webhook events. This turns an unpredictable HTTP request into a controlled workload.
Queues do not remove the need for limits. They relocate pressure. Limit job creation, cap queue concurrency, and define what happens when a downstream system is unavailable. For integrations, a queue paired with idempotency and reconciliation is usually more reliable than allowing clients to retry expensive synchronous calls indefinitely. See API idempotency for how to prevent retries from creating duplicate side effects.
Make 429 responses useful to legitimate clients
When a request exceeds a limit, the conventional HTTP response is 429 Too Many Requests. The response should tell a well-behaved client how to recover, without exposing unnecessary internal details.
- Return a stable error structure that distinguishes rate limiting from authentication, validation, and server errors.
- Provide a Retry-After value when the client can reasonably determine when another attempt may succeed.
- Expose documented limit and remaining-capacity information where appropriate. Header conventions should be consistent and treated as part of the API contract.
- Include a request or correlation identifier so support and engineering teams can trace the event.
- Do not suggest immediate repeated retries. A client that retries every time it receives 429 can amplify the overload.
Clients should use bounded exponential backoff with jitter. Backoff spreads retries over time; jitter prevents many workers that failed together from retrying together. The maximum delay, total attempt count, and retryable status codes should be explicit. A request that has exceeded a business deadline should be abandoned or moved to a later reconciliation process rather than retried forever.
Coordinate limits with authentication and integration contracts
Rate-limit behavior affects the entire integration contract. OAuth access tokens, API keys, webhooks, and service accounts may represent different callers and responsibilities. A webhook receiver should acknowledge quickly and process work asynchronously; applying a long synchronous workflow before acknowledgment can create repeated deliveries and unnecessary load.
For outbound integrations, distinguish your API's limit from the provider's limit. Track provider responses, honor documented retry signals, and use a central outbound scheduler rather than allowing every application worker to call the provider independently. This is especially important when multiple services share one provider credential.
Authentication and authorization decisions should occur before expensive processing, but do not assume that a rate limit can substitute for access control. For a broader treatment of access tokens, scopes, and integration identity, see OAuth 2.0 API authentication.
Design storage and enforcement for the deployment architecture
A rate limiter needs a counter or token state that is accurate enough for the policy and available to every relevant application instance. In a single-process prototype, memory may appear sufficient. In a horizontally scaled production system, process-local counters can let clients bypass limits simply by reaching different instances.
Shared state can be implemented through an appropriate distributed store or a gateway layer, depending on latency, consistency, failure tolerance, and operational ownership. The key questions are:
- Can all application instances evaluate the same policy?
- What happens if the limiter's state store is slow or unavailable?
- Should failure fail open for availability or fail closed for protection?
- How are counters partitioned by tenant, client, route, and deployment environment?
- Can policy changes take effect without inconsistent behavior during rollout?
There is no universal fail-open answer. A public read endpoint may prioritize availability, while an expensive administrative or financial operation may require stricter protection. Make the decision per class of endpoint, document it, and monitor the resulting risk.
Laravel and Python implementation choices
Laravel applications can place basic request throttling near routing or middleware, which is useful for common HTTP policies and keeps enforcement close to the application contract. For distributed deployments, the backing store and atomicity of counter updates matter more than the middleware syntax. Route-level policies should be supplemented with tenant-aware keys and separate treatment for queued jobs or provider calls.
Python services can implement limits in framework middleware, an API gateway, or a shared service layer. The choice depends on whether the policy must be consistent across multiple services and whether asynchronous workers share the same quota. In either ecosystem, avoid scattering hard-coded limits through controllers. Centralize policy definitions, make exceptions explicit, and test behavior across multiple instances and workers.
Framework facilities can accelerate delivery, but they do not decide the correct identity, business quota, provider coordination, or failure mode. Those are architecture and product decisions.
Monitor impact, not just rejected requests
A rate limiter is working only if its effects are visible. Monitor at least:
- 429 responses by tenant, client, route, and deployment version
- remaining-capacity or near-limit events where available
- latency and error rates for limited and unlimited traffic classes
- queue depth, job age, retry counts, and dead-lettered work
- downstream provider throttles and response latency
- authentication failures and suspicious traffic patterns
High 429 volume can mean abuse, a broken client, an undersized quota, a deployment regression, or a legitimate growth pattern. Compare limit events with successful business actions. If a customer repeatedly hits a limit while completing a normal synchronization workflow, the answer may be a better bulk endpoint, pagination, conditional requests, or asynchronous processing rather than simply raising the quota.
Operational ownership matters too. Define who can change a policy, how exceptions expire, and how clients are notified of planned changes. API versioning may be needed when changing semantics would surprise existing consumers; see API versioning strategy for contract-evolution considerations.
A pre-launch checklist for API rate limiting
- Identify the resources each endpoint consumes and classify expensive operations.
- Choose the limiting dimensions: tenant, user, client, IP, route, concurrency, or a combination.
- Select an algorithm that matches burst behavior and fairness requirements.
- Define 429 responses, retry guidance, headers, and stable error fields.
- Document client backoff, jitter, maximum attempts, and idempotency expectations.
- Test shared-state behavior across application instances, workers, and deployment failures.
- Coordinate limits with external provider quotas, queues, webhooks, and reconciliation jobs.
- Instrument limit events and establish an escalation path for legitimate clients.
- Review policy changes as contract changes, especially for external consumers.
Effective API rate limiting protects capacity while preserving predictable workflows for legitimate clients. The strongest implementations treat limits as one part of reliable integration engineering: authentication establishes identity, contracts define behavior, idempotency controls side effects, queues absorb asynchronous work, retries recover selectively, and observability reveals whether the system is serving its intended users. For ongoing API operations, support and maintenance can help keep those policies aligned with changing traffic, providers, and product requirements.


