
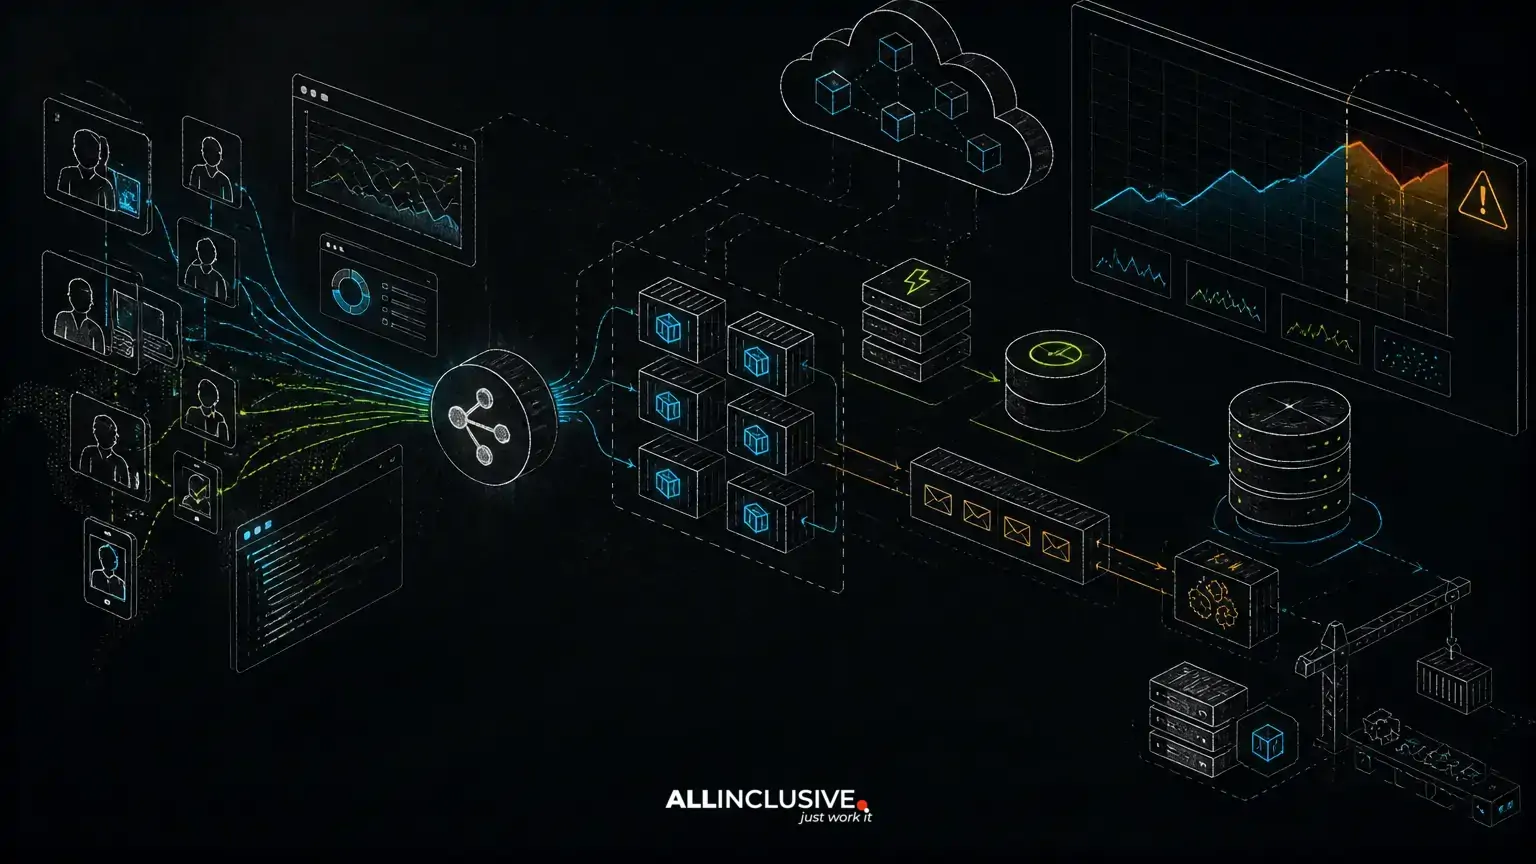
Load testing web applications is the process of applying controlled traffic to an application to learn how it behaves under expected and unusually high demand. The goal is not simply to discover the maximum number of requests a server can handle. A useful load test shows whether critical user workflows remain responsive, where capacity limits appear, how the system degrades, and whether the team can detect and recover from failure.
For a custom web application, this evidence should shape architecture and operations before launch. It can expose database contention, inefficient queries, exhausted connection pools, cache mistakes, slow external dependencies, queue overload, or deployment assumptions that are invisible during functional testing. The result is a more defensible release decision and a clearer plan for scaling on AWS or another cloud platform.
Start with user workflows, not request volume
A test that sends a large number of identical requests may produce a convenient number while saying little about production risk. Real traffic is a mixture of workflows with different costs and business consequences.
Begin by identifying the paths that must remain usable during demand spikes. Depending on the application, these may include:
- Anonymous page views and authenticated dashboard loads
- Login, password reset, or token refresh flows
- Search, filtering, sorting, and report generation
- Checkout, booking, form submission, or other transactional actions
- File uploads, exports, notifications, or AI-assisted operations
- Administrative actions that trigger background jobs
For each workflow, document the sequence of requests, expected payload sizes, authentication requirements, dependent services, and acceptable response time. Also record how frequently the workflow is expected to occur relative to others. A read-heavy application will need a different workload model from a system where every request performs a transaction and updates several tables.
Define success criteria before running the test
Load testing becomes difficult to interpret when the team decides what “good” means after seeing the results. Establish thresholds before the test, and separate user-facing objectives from infrastructure observations.
Useful criteria may include:
- Response-time targets for critical workflows, using percentiles rather than only averages
- Error-rate limits for each workflow and for the application overall
- Throughput targets such as completed transactions or processed jobs
- Acceptable queue age and backlog during asynchronous work
- Database CPU, connection utilization, lock contention, and query latency limits
- Resource headroom needed for deployments, failover, and normal traffic variation
An average response time can hide a poor experience for a small but important group of users. Track percentile latency, such as the p95 or p99, alongside averages and maximums. The exact thresholds depend on the workflow and business context; a report export may tolerate more delay than a payment confirmation or inventory update.
Build a production-like test environment
Results from a developer laptop or a small staging instance rarely predict production behavior. The environment does not need to be an exact replica in every respect, but the components that determine capacity should be representative.
Review the following before testing:
- Application runtime, web server, container image, and process configuration
- Database engine, schema, indexes, data volume, and connection pool settings
- Redis or another cache, including memory limits, eviction behavior, and key patterns
- Queue workers, broker configuration, retry behavior, and concurrency
- Object storage, email, payment, search, and other external dependencies
- Load balancers, autoscaling policies, network paths, and TLS termination
Use realistic data distributions rather than a handful of small records. Query plans, cache hit rates, index behavior, and serialization costs can change materially as data grows. If production dependencies cannot be exercised safely, use controlled substitutes and document the limitation. A test that excludes a slow external API should not be presented as a complete end-to-end result.
Choose load patterns that reveal different failures
One test profile cannot answer every capacity question. A sensible test plan combines several patterns:
- Baseline load: establishes normal latency, resource use, and error behavior.
- Ramped load: increases traffic gradually to reveal the first saturation point.
- Peak load: represents a known campaign, launch, batch event, or seasonal demand.
- Stress load: exceeds the expected level to observe degradation and failure boundaries.
- Spike load: introduces a rapid increase to test autoscaling, queues, and connection handling.
- Soak load: holds a sustained workload long enough to expose leaks, accumulation, or gradual degradation.
These tests answer different operational questions. A ramp test may reveal database saturation, while a soak test may expose memory growth or a queue that never catches up. A spike test can show that the application is healthy at a steady rate but cannot absorb an abrupt arrival pattern.
Instrument the application before interpreting results
Load-test output tells you that a workflow slowed down. It does not automatically explain why. Instrumentation must connect user-facing latency to application, database, cache, queue, and infrastructure behavior.
At minimum, collect:
- Request rate, response status, latency percentiles, and timeout counts
- CPU, memory, disk, network, container restarts, and instance health
- Database query duration, slow-query samples, locks, connections, and replication health where applicable
- Cache hit and miss behavior, memory usage, evictions, and command latency
- Queue depth, job age, processing time, retry count, and dead-letter activity
- External dependency latency, timeout rates, and circuit or fallback behavior
Correlated logs, metrics, and traces make diagnosis faster. For example, a slow checkout request paired with database lock waits suggests a different remedy from the same request paired with an exhausted worker pool. Detailed observability guidance is covered in web application observability.
Find the bottleneck instead of adding servers blindly
When latency rises, increasing instance count may help, but only if the constrained resource scales horizontally and the rest of the architecture can support the change. Common bottlenecks include:
Application workers and connection pools
Too few web workers can create a queue before requests reach application code. Too many workers can exhaust memory or overwhelm the database. Database connection pools require similar care: a larger pool may reduce waiting locally while creating excessive concurrent work downstream.
Database queries and contention
Load often exposes missing indexes, inefficient joins, unbounded result sets, repeated queries, and writes contending on the same rows. Optimize the query and access pattern before treating database scaling as the first response. Read replicas can help specific read workloads, but they do not remove write contention or make every query safe to replicate.
Cache design
Caching can reduce repeated database work, but it introduces invalidation, consistency, memory, and stampede risks. Test both warm-cache and cold-cache behavior. A cache strategy should identify which data can be stale, how keys are invalidated, and what happens when Redis is unavailable. See the related guide to Redis caching strategy.
Background processing
Moving expensive work to a queue can protect the request path, but it does not eliminate the work. Measure queue age and completion time under load. Without bounded retries, idempotent handlers, and backpressure, a spike can create a backlog that continues growing after web traffic returns to normal. The article on queue architecture for web applications explains these controls.
Use Docker and CI/CD to make testing repeatable
Containerized application components can make load-test environments easier to reproduce, provided the image, configuration, data setup, and dependency versions are controlled. Docker does not make a test production-equivalent by itself; it simply improves consistency when the surrounding infrastructure is modeled correctly.
Put the test scenario and environment setup under version control. A CI/CD pipeline can run a small smoke load test on every suitable change, then reserve longer ramp, stress, or soak tests for scheduled runs and release candidates. The pipeline should publish results, preserve the tested commit and configuration, and fail or require review when agreed thresholds are exceeded. This connects performance evidence to delivery rather than leaving it as a one-time exercise. See CI/CD for web applications for the broader release-pipeline context.
Test failure, recovery, and deployment behavior
Capacity is only one part of operability. A system may tolerate normal peak traffic and still create unacceptable risk if it cannot recover cleanly from a failed instance, exhausted dependency, or interrupted deployment.
During controlled tests, verify that:
- Autoscaling responds without creating connection storms or uneven capacity
- Health checks remove unhealthy instances without routing users into repeated failures
- Queue retries are bounded and failed jobs become visible for investigation
- Timeouts prevent slow dependencies from consuming every worker
- Deployments preserve availability and do not mix incompatible application and schema versions
- Logs, alerts, dashboards, and traces allow operators to identify the failing layer
- Backups can be restored and recovery objectives are realistic for the business
Zero-downtime deployment is not merely a load-balancer setting. Schema changes, cache compatibility, background workers, and long-running requests all affect whether a release can be rolled out safely. Review zero-downtime deployment patterns alongside performance testing.
Turn test results into launch decisions
A useful report records more than a graph of requests per second. Include the tested commit, environment, dataset, workload mix, duration, ramp pattern, dependency assumptions, thresholds, observed results, and known limitations. For each bottleneck, state the evidence, likely cause, remediation, and retest condition.
Launch decisions should distinguish among three outcomes:
- Ready for the tested envelope: critical workflows meet their criteria with documented headroom and monitoring.
- Ready with controls: launch is acceptable if traffic is limited, a feature is staged, a queue is bounded, or an on-call and rollback plan is in place.
- Not ready: critical workflows fail thresholds, recovery is unclear, or the bottleneck has no safe operational response.
After launch, repeat tests when the data model, traffic profile, infrastructure, major dependencies, or core workflows change. Performance is a property of the complete system, not a permanent characteristic of a single server size.
Plan load testing as part of custom application delivery
Load testing is most effective when it begins during architecture and product planning, not immediately before release. The team can then make deliberate choices about stateless web processes, database ownership, caching, queues, cloud capacity, observability, deployment strategy, and disaster recovery.
For organizations building or extending a custom web application, custom web development should include an explicit operational model: which workflows matter most, what can be asynchronous, what must remain strongly consistent, how capacity will be measured, and who owns recovery. Allinclusive can also support the ongoing monitoring, maintenance, and incident-readiness work described in support and maintenance services.
The breaking point is not a single number. It is the point at which a defined workflow, dependency, or recovery process no longer meets its business requirement. Finding that boundary before launch gives product and engineering teams time to fix the architecture, adjust the operating plan, or narrow the release envelope while the choices are still manageable.


