
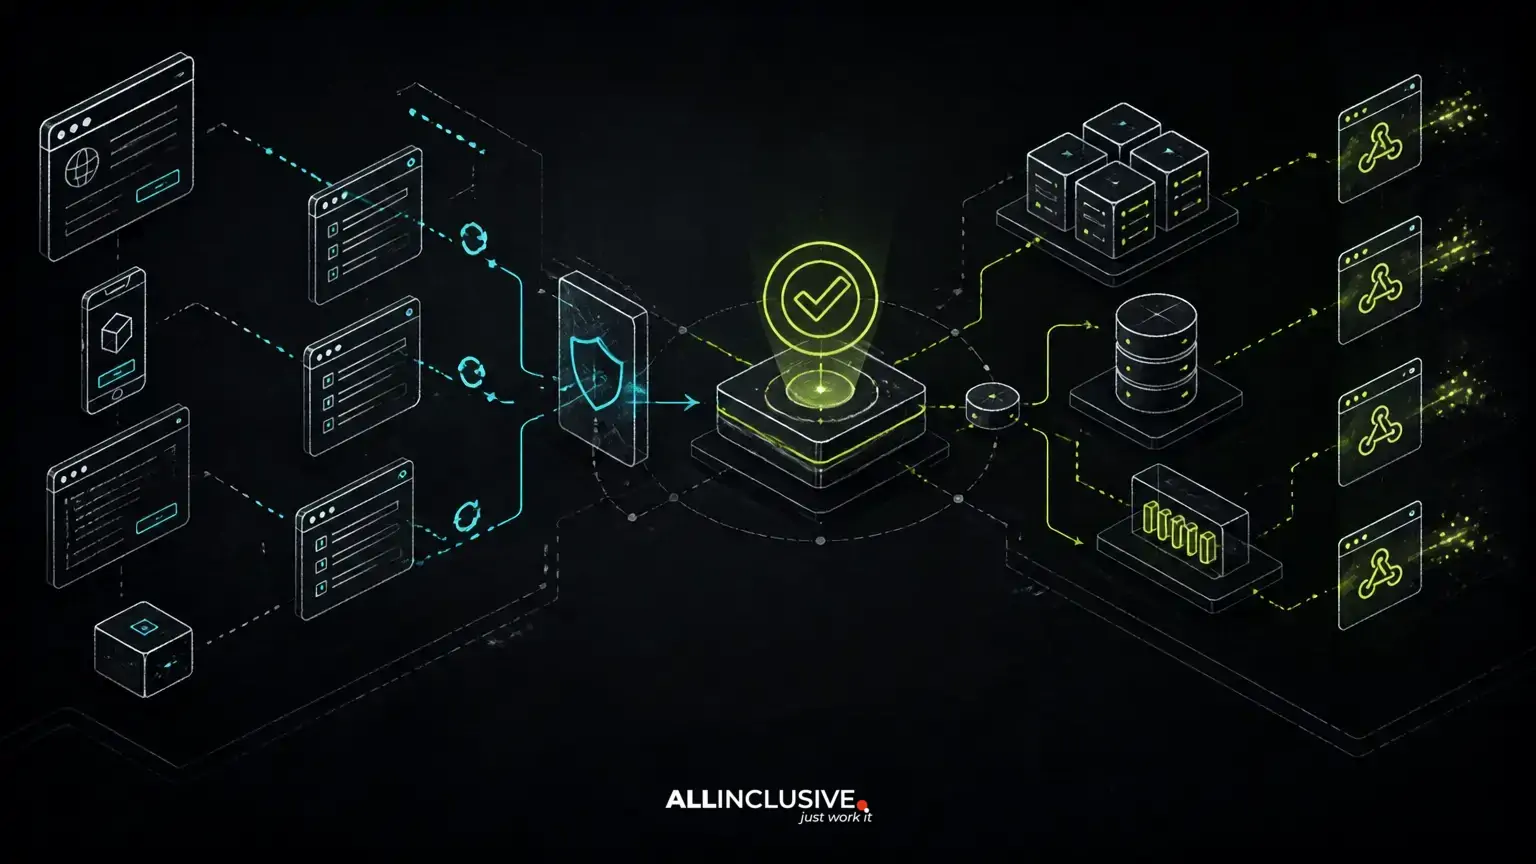
API idempotency is the design property that allows a client to repeat the same logical request without causing the same side effect more than once. It is essential for payment attempts, order creation, subscription changes, inventory reservations and webhook processing because networks fail, clients retry and distributed systems deliver messages more than once. A related decision for api idempotency is covered in custom software development.
The usual implementation is an idempotency key supplied by the client. The server associates that key with the intended operation, stores the result, and returns the original result when the same operation is submitted again. That sounds simple, but reliable behavior depends on defining the operation boundary, handling concurrent requests, preserving request consistency and deciding how long a key remains valid.
For teams building or integrating APIs, idempotency is part of a larger reliability design that includes API development, authentication, validation, retries, queues, reconciliation and observability.
Why duplicate side effects happen in otherwise correct APIs
HTTP requests can fail after the server has completed the work but before the client receives the response. A client may then retry, creating a second order or charging a customer twice. Similar conditions occur when:
- A mobile application loses connectivity while submitting a form.
- An API gateway or SDK retries a request after a timeout.
- A queue delivers a message again after a worker crashes before acknowledging it.
- A webhook provider retries because the receiving endpoint responded too slowly or returned an error.
- A user double-clicks a purchase or submission button.
At-least-once delivery is common in integrations because it favors not losing work. The consequence is that consumers must tolerate duplicates. A server that simply executes every valid request cannot distinguish an intentional second purchase from a retry unless the client and API share an idempotency mechanism.
What an idempotency key should represent
An idempotency key should identify one intended operation, not merely one network request. For example, a checkout application might generate a unique key when the customer confirms an order and reuse it for every retry of that order attempt. It should not generate a new key each time a timeout occurs.
A useful request model typically includes:
- Idempotency key: a client-generated, sufficiently unique identifier.
- Operation scope: the endpoint, account, tenant or resource context to which the key applies.
- Request fingerprint: enough information to detect reuse of the key with materially different input.
- Stored outcome: the status and response that represent the first completed attempt, including relevant error results.
- Retention policy: the period during which the key can safely identify the same operation.
Scope matters. A key that is globally unique is easier to reason about, but a scoped key can be sufficient if the storage lookup includes the authenticated customer or tenant. The design should prevent one client from replaying or colliding with another client’s operation.
How the server should process an idempotent request
A robust request path reserves the key before performing the side effect. The simplified sequence is:
- Authenticate the caller and validate the request shape.
- Normalize the operation context and calculate a request fingerprint.
- Atomically create an idempotency record for the key.
- If the key already has a completed result, return that stored result.
- If another request is processing the same key, return a clear in-progress response or wait according to the API contract.
- Perform the business operation within the appropriate transaction boundary.
- Store the resulting status and response, then release the processing state.
The atomic reservation is critical. A check-then-insert sequence can race when two identical requests arrive at nearly the same time. A database uniqueness constraint, conditional write or equivalent atomic operation should enforce one owner for the key.
The idempotency record and business data also need a deliberate consistency strategy. When both can be committed in one database transaction, the relationship is easier to guarantee. When the side effect crosses a service boundary, an outbox, workflow state or reconciliation process may be needed instead of pretending that one transaction covers every system.
Handling key reuse, mismatched requests and in-progress work
Reusing a key with different business data is not a harmless mistake. If a key originally represented a $100 payment and is later sent with a $200 amount, silently returning or executing a result can create an accounting defect. APIs should compare a request fingerprint or relevant immutable fields and reject a mismatch with a clear client error.
Concurrent requests require a separate state from completed results. Useful states can include processing, succeeded, failed and expired. The response for a request that encounters an active processing record should tell the client whether to retry later, poll a status endpoint or treat the operation as unresolved.
Do not automatically cache every failure without considering its cause. A deterministic validation failure can safely be replayed. A temporary dependency timeout may need a retry policy, while an ambiguous payment result may require reconciliation rather than another charge attempt. The API contract should document which outcomes are stored and how clients recover.
Idempotency for payments, orders and inventory
Payments
Payment operations need especially careful boundaries. The idempotency key should cover the creation of one payment attempt, not an entire customer journey if the customer may intentionally try again with a different payment method. Store the amount, currency, customer context and provider reference needed to detect mismatches and reconcile uncertain outcomes.
If a payment provider has its own idempotency facility, the application may need to pass a stable key through to that provider while retaining its own record. These are separate reliability boundaries: preventing duplicate application orders does not automatically prevent duplicate provider charges.
Orders
For order creation, the key should identify the customer’s intended order submission. The system should decide whether inventory reservation, tax calculation, fulfillment creation and payment authorization belong to one operation or several coordinated steps. A single idempotency key may protect order creation, while downstream services use their own operation identifiers.
Inventory and other state changes
Idempotency does not mean every endpoint can be safely retried without considering business semantics. “Set inventory to 20” is naturally easier to repeat than “decrement inventory by 1.” For increment and decrement operations, use a unique command identifier, a version check or a ledger-like event model so a repeated command is not applied twice.
Webhooks, queues and asynchronous workflows
Inbound webhooks should be treated as potentially duplicated and out of order. Persist the provider’s event identifier when available, enforce uniqueness, acknowledge quickly when appropriate and process the business effect through a durable worker. A duplicate event can then be recognized without repeating the side effect.
Queue consumers need the same discipline. A worker may complete an operation and crash before acknowledging the message, causing redelivery. Store a durable operation identifier and make the handler safe to run again. If exactly-once business behavior is required, it is usually achieved through idempotent application logic and durable state, not by assuming the transport will deliver exactly once.
For long-running workflows, expose status rather than holding an HTTP connection open. The initial request can create a workflow record keyed by the idempotency key, while later requests retrieve its state. This separates request retries from workflow progress and gives support teams a way to investigate unresolved operations.
Laravel and Python implementation choices
In Laravel, an idempotency layer can be implemented as middleware or an application service that authenticates the request, validates the key, and coordinates a database-backed record. Laravel’s database transactions, queue infrastructure and cache abstractions can support the design, but the critical uniqueness and transaction rules still belong in the data model and business workflow. A cache alone is risky for financial or order records unless the durable source of truth is elsewhere.
In Python services, the same responsibility may live in framework middleware, a dependency, or a command-handling service. SQL constraints, transactional boundaries and explicit worker state are more important than the choice between common Python web frameworks. Async applications should also define how concurrent coroutines or workers claim the same key and how cancellation affects the processing record.
In either stack, keep idempotency logic close enough to the operation to understand its business consequences. Generic middleware can reserve keys, but it may not know whether an error is retryable, whether a downstream provider has accepted a request, or which response should be retained.
Observability and reconciliation for ambiguous outcomes
Idempotency reduces duplicates; it does not eliminate uncertainty. A timeout can still leave the application unsure whether a payment provider or external ERP completed its work. Reliable integrations need reconciliation paths that compare local operation records with provider or partner state.
Capture structured data such as:
- Idempotency key and internal operation identifier.
- Authenticated tenant, account or customer scope.
- Request status and processing duration.
- Dependency request identifiers and response classifications.
- Number of retries, duplicate detections and key mismatches.
- Age of unresolved operations and reconciliation outcomes.
Protect sensitive values in logs and avoid treating an idempotency key as a secret. Metrics should distinguish successful replays from duplicate attempts, mismatched reuse, stuck processing records and downstream ambiguity. These signals help teams identify client bugs, failing dependencies and workflow gaps.
For broader API measurement, pair this design with the practices described in API monitoring and observability. If the integration also depends on quotas or burst control, API rate limiting should be designed alongside retries so clients do not amplify an outage.
Implementation checklist for an idempotent API
- Define which operations create side effects and require idempotency.
- Document key format, scope, retention and reuse behavior.
- Enforce atomic key creation with a durable uniqueness rule.
- Compare repeated requests for meaningful input changes.
- Represent processing, completed, failed and unresolved states explicitly.
- Specify client behavior for timeouts, conflicts, in-progress requests and validation errors.
- Make webhook and queue handlers safe under redelivery.
- Separate application idempotency from provider-specific idempotency.
- Use reconciliation for external operations with ambiguous outcomes.
- Test concurrent submissions, lost responses, worker crashes, duplicate webhooks and expired keys.
Idempotency is not a decorative header added after an integration fails. It is a contract between clients, services and external providers about what a retry means. When the contract is backed by atomic storage, explicit workflow states and useful observability, teams can retry safely without hiding failures or creating duplicate business records.
For ongoing reliability work after launch, support and maintenance can include monitoring, integration changes, incident investigation and controlled improvements as dependencies and business rules evolve. Related contract decisions are covered in API versioning strategy, which helps preserve compatibility as idempotency behavior and error responses mature.


