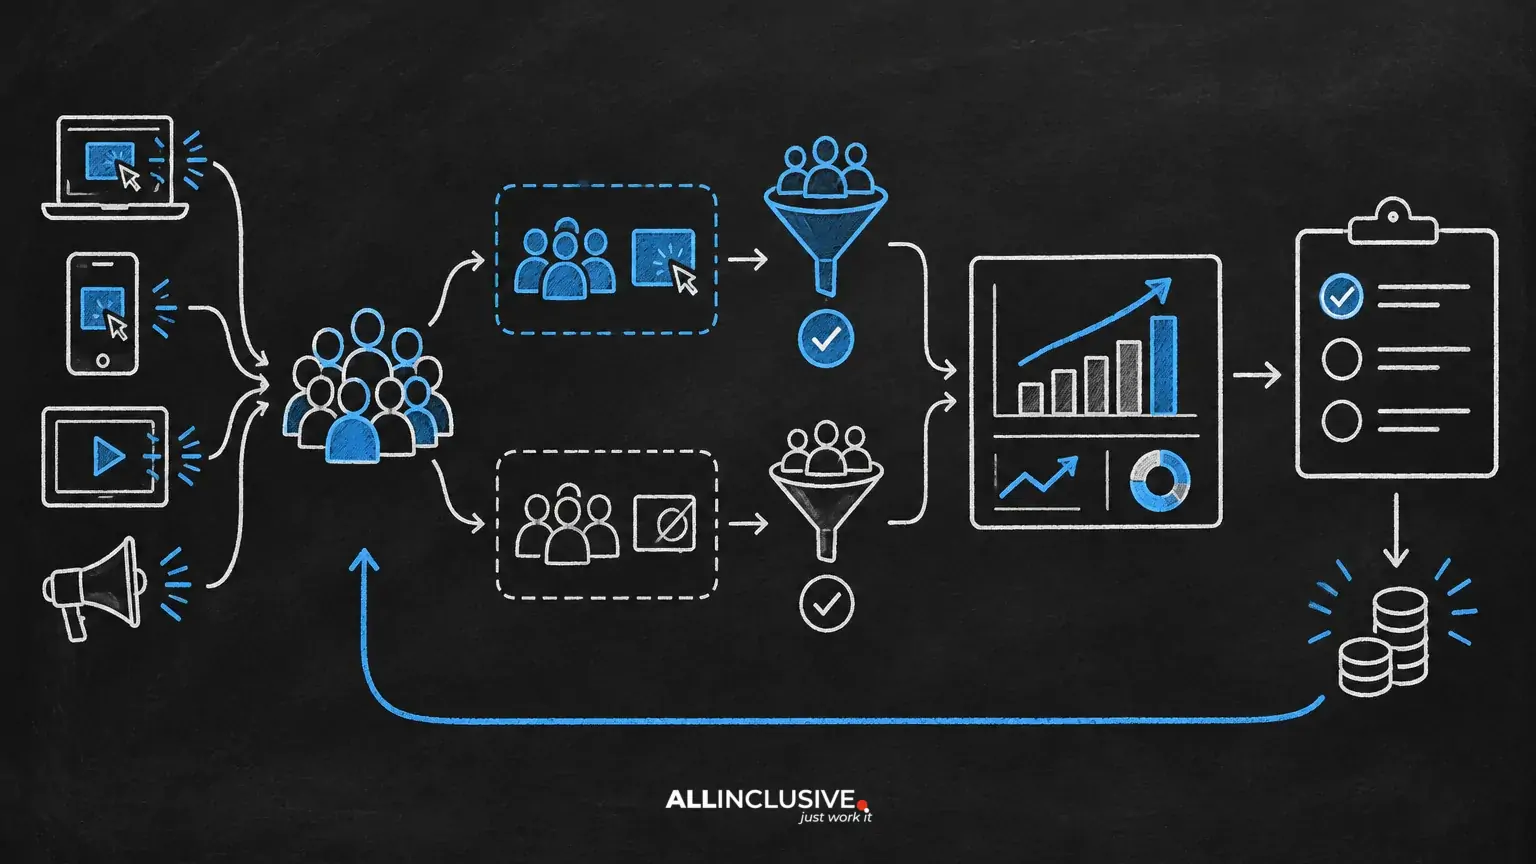
Incrementality testing for paid media answers a question that platform reporting alone cannot: what additional outcomes did advertising actually cause? A platform may claim credit for a conversion because an ad impression or click appeared before it. An incrementality test compares outcomes with advertising against a credible estimate of what would have happened without it.
The result is not a replacement for attribution, conversion tracking, or financial reporting. It is a decision-making layer that helps teams evaluate whether a campaign, channel, audience, or tactic creates incremental value—and whether the next dollar should remain invested there.
What incrementality means in paid media
Incrementality is the difference between observed results with advertising and the results that would have occurred in the absence of that advertising. The second figure is called the counterfactual. Because a business cannot observe both conditions for the same person at the same time, testing requires a control design or another credible method for estimating the counterfactual.
A simple expression is:
Incremental conversions = conversions in the treatment group − expected conversions without the treatment
For example, suppose an audience exposed to a campaign generates 1,000 purchases. If a comparable holdout group indicates that 900 purchases would have occurred without the campaign, the estimated incremental effect is 100 purchases. The example illustrates the method only; actual results depend on test design, sample size, measurement quality, and business context.
This distinction matters because reported conversions can include people who were already likely to buy, conversions influenced by other channels, and conversions that would have happened after an organic visit or direct interaction.
Why platform attribution is not an incrementality test
Attribution assigns credit according to a defined rule. Incrementality estimates causal impact. Those are related but different questions.
- Attribution asks: Which touchpoint received credit under the selected model?
- Incrementality asks: How many additional outcomes occurred because the advertising ran?
- Efficiency reporting asks: What revenue or profit was generated relative to spend?
A campaign can show strong attributed ROAS while producing limited incremental demand, particularly when it reaches people already close to converting. Conversely, a prospecting campaign may receive less visible credit in a last-touch report while contributing meaningful incremental outcomes.
Use attribution for operational optimization and path analysis. Use incrementality when the decision involves causal confidence, budget allocation, channel expansion, audience suppression, or the value of reducing spend.
For a broader view of the limitations of platform-reported efficiency, see Paid Media ROAS: Why Platform ROAS Is Not the Whole Story.
Core approaches to incrementality testing
Randomized holdout tests
A randomized holdout test divides eligible users, households, accounts, geographic areas, or other units into treatment and control groups. The treatment group is eligible to receive the campaign or tactic; the control group is deliberately withheld or placed in a condition that represents the absence of that tactic.
Randomization is valuable because it helps balance known and unknown differences between groups. The key requirement is that the control group remains a credible representation of the treatment group’s expected outcome without advertising.
Holdouts can test questions such as:
- Does branded search create additional conversions, or mostly capture existing intent?
- Does retargeting generate purchases beyond those likely to occur organically?
- Does a new prospecting audience create incremental revenue after accounting for overlap?
- Does increasing exposure produce additional outcomes, or only additional attributed activity?
Geographic or regional tests
When user-level assignment is unavailable or unsuitable, businesses can compare treatment and control geographies. One set of markets receives the advertising change while another set does not, ideally with markets selected for similar historical trends and business conditions.
Geographic tests can be practical for broad media programs, offline businesses, and campaigns where exposure cannot be reliably controlled at the user level. They also introduce risks: markets may differ in demand, distribution, competition, seasonality, or media spillover. A geographic design usually benefits from pre-test trend analysis and a clearly defined comparison method.
Time-based and matched-market designs
Some tests compare performance before and after a change or use matched markets to estimate what would have happened without it. These approaches can be useful when randomization is not possible, but they are more exposed to confounding factors such as promotions, pricing, inventory, seasonality, and changes in the sales process.
Time-based evidence should therefore be described with appropriate caution. A post-campaign increase is not automatically proof of incrementality.
How to design an incrementality test
1. Start with a decision, not a metric
Define the business decision before selecting the test. Possible decisions include maintaining spend, increasing a channel’s budget, reducing retargeting, changing audience exclusions, or reallocating investment to another tactic.
A useful test brief states:
- The tactic or campaign being tested
- The eligible population or geography
- The treatment and control conditions
- The primary business outcome
- The test duration and decision window
- The minimum effect that would change the decision
2. Choose the right unit of assignment
The assignment unit should match how exposure and outcomes behave. Users may be suitable for some digital campaigns, while households, accounts, stores, or regions may be more appropriate for other businesses.
Be careful with interference. If people in the control group can still receive the campaign through another device, account, channel, or audience, the measured difference may be understated. If treatment exposure reaches the control group through geographic spillover, the test is also weakened.
3. Protect the control group
A holdout is only useful if the control condition is maintained. Document which campaigns, audiences, placements, and automated systems are included or excluded. Establish who can change the setup and how deviations will be recorded.
In some environments, a complete advertising blackout is impractical. In that case, define the control condition precisely—for example, exclusion from a specific campaign or tactic rather than from all paid media—and interpret the result accordingly.
4. Select a primary outcome
Choose an outcome connected to the business decision. Revenue, qualified leads, activated accounts, subscriptions, or contribution margin may be more useful than clicks or platform conversions. Secondary metrics can explain the result, but changing the primary metric after viewing the data reduces confidence in the conclusion.
For lead-generation programs, the outcome should ideally extend beyond form completion. Connecting media exposure to qualified pipeline or revenue may require the data practices described in Offline Conversion Tracking: Connecting Leads to Revenue.
5. Estimate required scale and duration
The test needs enough observations to distinguish a meaningful effect from normal variation. Required scale depends on baseline conversion rates, expected lift, outcome volatility, the number of markets or users, and the business cost of a wrong decision.
Do not select a short test simply because it is convenient. The measurement window should reflect the conversion cycle and allow sufficient time for delayed conversions, sales qualification, or repeat purchases when those are part of the decision.
6. Freeze the main hypothesis before launch
Write down the hypothesis, primary outcome, test population, analysis method, and success threshold in advance. This reduces the temptation to search for a favorable segment or metric after results are available.
How to read lift results
Incrementality results are commonly expressed as absolute lift, relative lift, incremental conversions, incremental revenue, or incremental return on ad spend.
- Absolute lift: the difference in outcome rate between treatment and control.
- Relative lift: the difference expressed relative to the control outcome rate.
- Incremental outcomes: the estimated additional conversions, customers, or revenue attributed to the treatment.
- Incremental efficiency: incremental value divided by media spend, with the value definition stated clearly.
Always review uncertainty around the estimate. A measured lift that is small relative to expected variation should not be treated as a precise result. A result with no clear evidence of lift is not necessarily proof that the channel has no value; it may reflect insufficient scale, contamination, a weak control, a short test, or an outcome that was poorly chosen.
Also check whether the test measured the intended exposure. If delivery was materially lower than planned, or treatment and control differed for reasons unrelated to the campaign, the result may not answer the original question.
Turning test results into budget decisions
A useful decision framework combines incremental impact with economics and strategic constraints.
Scale when marginal economics remain attractive
If the test indicates meaningful incremental value and the tactic meets the organization’s profitability threshold, scaling may be justified. The next dollar may not perform like the test period, so treat the result as evidence for a budget range rather than a permanent guarantee.
Maintain when the result is useful but uncertain
When the measured effect is directionally positive but uncertain, maintain a controlled level of investment and run a stronger follow-up test. This is often more rational than either immediate expansion or an abrupt shutdown.
Reduce or stop when incrementality is weak
If a well-designed test finds little incremental value, consider reducing the tactic, changing its role, or testing a narrower audience. Before acting, rule out measurement failure and examine whether the tactic is necessary for another strategic reason, such as reaching a priority audience or supporting a broader media system.
Use results to improve attribution assumptions
Incrementality can calibrate how much confidence to place in channel-reported conversions. It should not be used to create a new arbitrary credit rule, but it can reveal where attributed performance materially overstates or understates causal contribution.
Common testing mistakes
- Testing without a decision rule: collecting data without knowing what action the result should inform.
- Using a weak control: comparing groups that differ in intent, geography, eligibility, or sales access.
- Allowing contamination: exposing control units through overlapping campaigns or channels.
- Changing the campaign during the test: introducing creative, bidding, budget, or targeting changes that complicate interpretation.
- Optimizing to an early signal: judging a test on clicks or immediate conversions when the business outcome occurs later.
- Ignoring external events: overlooking promotions, inventory issues, competitor activity, or seasonality.
- Confusing statistical confidence with business value: treating a measurable effect as worthwhile without considering margin, capacity, or customer quality.
How incrementality fits with attribution, MMM and dashboards
No single measurement method answers every paid-media question. Attribution provides detailed path and campaign reporting. Incrementality tests provide causal evidence for selected interventions. Marketing mix modeling can help evaluate channel contributions over longer periods and at broader levels, especially when user-level data is limited. The methods should be considered complementary rather than interchangeable.
For context on when broader modeling may be appropriate, read Marketing Mix Modeling for Paid Media: When MMM Becomes Useful. Operational reporting can then bring spend, attributed outcomes, incremental results, and assumptions into one decision view; the Paid Media Dashboard: Metrics Executives and Operators Actually Need guide covers that reporting layer.
A practical operating model
Teams do not need to test every campaign continuously. A more sustainable approach is to prioritize tests where uncertainty is high and the budget decision is consequential.
- Rank channels and tactics by spend, strategic importance, and uncertainty about incremental value.
- Define a testable intervention and a control condition.
- Document the primary outcome, analysis plan, and decision threshold.
- Run the test without unnecessary changes.
- Review lift, uncertainty, delivery quality, and business economics together.
- Record the conclusion, limitations, and next action in a shared measurement log.
- Retest when the audience, creative, offer, funnel, or market conditions materially change.
The strongest incrementality programs are not built around a single impressive result. They create a repeatable process for learning where paid media adds demand, where it mainly captures existing demand, and how that evidence should shape future investment.
Explore the broader paid media resource hub for related measurement and optimization guidance.