
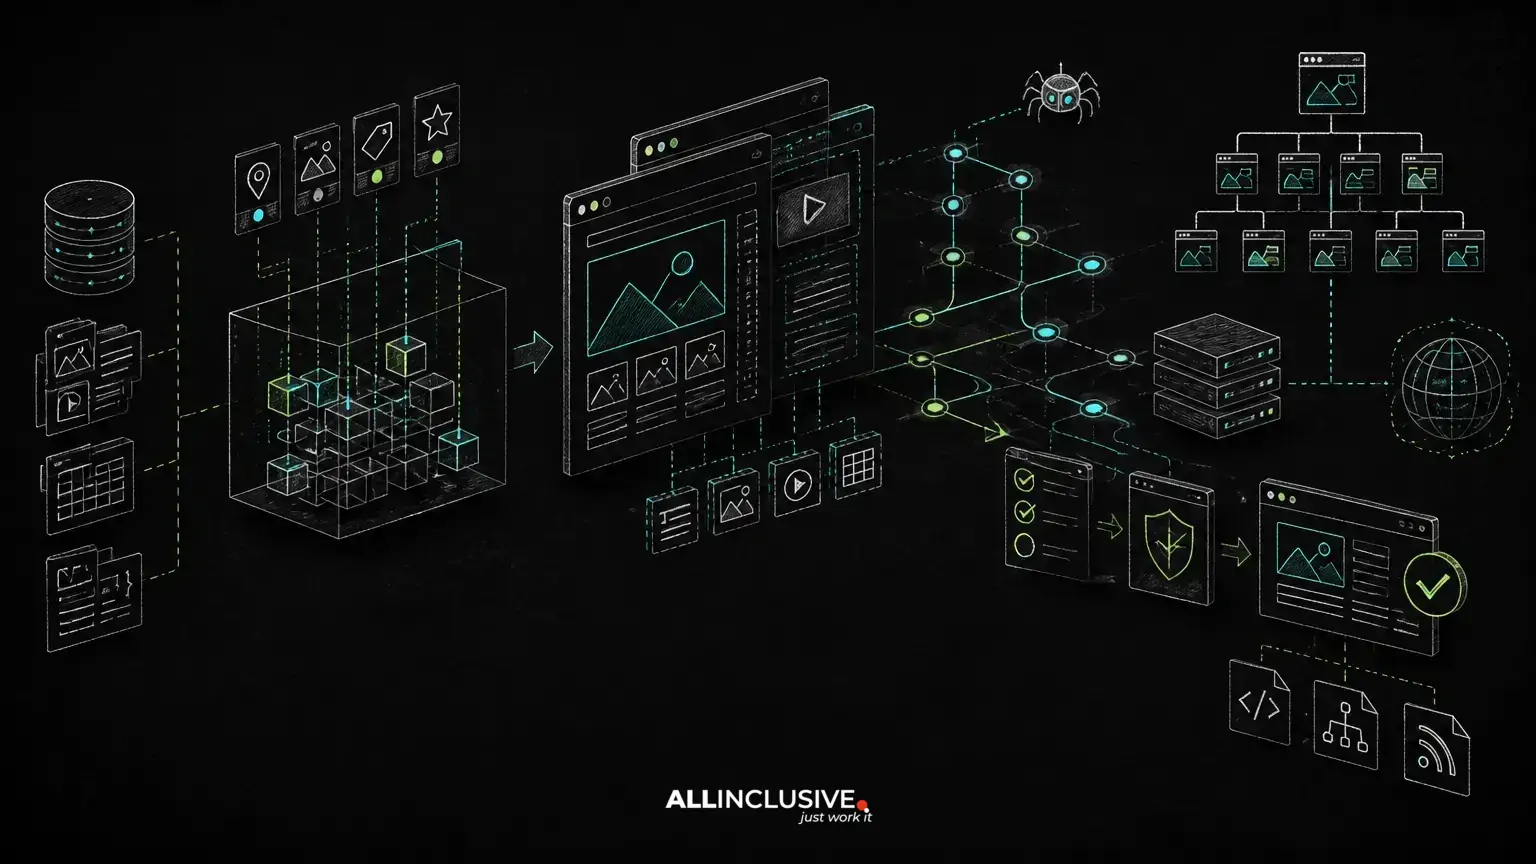
Programmatic SEO in a custom CMS is the controlled generation of search-focused pages from structured data, reusable templates and publishing rules. The objective is not to create the largest possible URL set. It is to make useful, distinct pages repeatably while preserving editorial quality, crawl efficiency and operational control.
A well-designed system connects the content model to routing, rendering, metadata, canonicals, structured data, internal links, media and indexation. That connection matters because SEO defects are often architecture defects: an incomplete record can produce a weak page, a routing change can create duplicate URLs, and an automated sitemap can expose pages that should not be indexed.
This article explains the main components of a programmatic SEO architecture and the guardrails a custom CMS should provide. A custom-made platform can implement these controls around an existing editorial workflow rather than forcing marketers and developers to manage disconnected tools.
What programmatic SEO should do inside a custom CMS
Programmatic SEO works best when each page represents a legitimate combination of data, user intent and editorial value. Typical examples include product directories, integration pages, resource libraries, property or inventory records, technical documentation, comparison datasets and other structured collections.
The CMS should treat a programmatic page as a governed content object, not merely a URL generated from a database row. That object may include:
- A stable identifier and canonical route.
- Structured attributes used by the template and filters.
- Page-specific title, description and social metadata controls.
- Editorial status, review ownership and publication dates.
- Indexation eligibility and canonical settings.
- Related records used for internal linking.
- Media assets with defined crops, dimensions and alternative text.
This model gives product and marketing teams visibility into what will be published, while developers retain control over validation, rendering and release behavior.
Start with a data model that can support useful pages
The quality of a programmatic SEO system is constrained by the quality and completeness of its source data. If a template relies on five meaningful attributes but only two are populated consistently, the result may be a collection of near-identical pages with little value to users.
Before building templates, identify the user questions each page must answer. Then map those questions to required, optional and derived fields. A product directory might need specifications, supported use cases, compatibility details, documentation links and related products. A location-independent service dataset might need service attributes, eligibility rules and proof points rather than simply a modified heading.
Use validation at the data-entry boundary. Required fields should block publication when their absence would make the page incomplete. Conditional rules can handle cases such as requiring a technical specification only for certain product types. Derived fields should be generated consistently rather than copied manually into multiple records.
The CMS should also distinguish between a record that exists and a record that is publishable. Draft, review, approved, scheduled, published, archived and suppressed states are more useful than a simple active/inactive flag. This supports an editorial workflow in which subject-matter experts can review generated content before it becomes indexable.
Build templates as page systems, not text substitution
A weak programmatic template replaces a variable in a fixed paragraph. A stronger template assembles meaningful page sections from the record, shared content blocks and editorial rules.
For each template, define:
- Which fields appear above the fold and which support deeper evaluation.
- How missing data is handled without leaving empty headings or awkward filler.
- Which sections are shared across the collection and which are record-specific.
- How related pages are selected and labeled.
- What constitutes enough information for publication.
- Which components are rendered server-side and which, if any, require client-side behavior.
Templates should support controlled variation without making quality unpredictable. For example, a page can display different specification groups based on product type while preserving a consistent information hierarchy. Reusable blocks can provide editorial context, but they should not be used to disguise pages that lack unique substance.
Server-rendered HTML is often a straightforward choice for content-led programmatic pages because the primary content, links and metadata are available in the initial response. A Laravel or PHP implementation can render these views from validated CMS data while keeping interactive enhancements separate from the crawlable document. Other architectures can use the same principle: make the content experience robust before adding browser-dependent behavior.
Use routing rules to protect URL consistency
Programmatic systems can create thousands of URLs, so routing must be deterministic. A record should have one preferred public path, with redirects or canonical handling for legacy paths, aliases and changed slugs.
Define rules for:
- Slug creation, normalization and reserved words.
- Case, trailing slash and parameter behavior.
- Deleted, archived and merged records.
- Pagination, filtering and sorting URLs.
- Language or regional variants, where applicable.
- Historical URL redirects after a name or category change.
Faceted navigation deserves particular care. Filter combinations may help users but should not automatically become indexable landing pages. The CMS should distinguish navigational URLs from intentionally curated SEO pages, with explicit rules for which combinations receive a canonical URL, an indexable template and inclusion in XML sitemaps.
Routing logic should be tested independently from page content. A content release should not unexpectedly create duplicate routes, and a slug update should not silently break internal links or external references.
Make metadata, canonicals and schema data-driven but reviewable
Programmatic metadata should be generated from structured fields, but automation does not mean removing editorial control. The CMS should provide a default formula, preview behavior and override fields for exceptions.
Useful controls include:
- Template-level title and description patterns.
- Record-level overrides for important pages.
- Length and duplication warnings rather than arbitrary truncation.
- Open Graph and social image selection.
- Canonical URL generation based on the preferred route.
- Robots directives that are separate from canonical settings.
Canonicalization should describe the preferred version of substantially equivalent content; it should not be used to make thin or irrelevant pages appear valuable. Likewise, a noindex directive is not a substitute for preventing low-value combinations from being generated or linked at scale.
Structured data can be assembled from the same validated model, but schema type selection must reflect the page’s actual content. Add fields only when the CMS has reliable values and the rendered page supports them. Validation should happen during preview and, where practical, in deployment or publishing checks. The programmatic seo custom cms workflow also connects to the guidance in schema markup automation in a custom CMS.
Design indexation as a publishing decision
Indexation should be an explicit outcome of workflow, not an accidental consequence of a database query. A page may be complete enough for internal use but not ready for search. It may also be useful to users while intentionally remaining out of the public index.
Model indexation eligibility using conditions such as:
- Required content fields are complete.
- The record has passed editorial review.
- The page has a stable canonical route.
- The content is not substantially duplicative of another page.
- Any required supporting links or media are present.
- The record is current enough to justify publication.
Keep the logic observable. Editors should be able to see why a page is not indexable, and developers should be able to inspect the rule that produced the result. A preview should show the rendered title, canonical, robots directive, structured data and sitemap eligibility before publication.
Indexation controls should also account for lifecycle events. When a record is retired, the correct response may be a redirect, a useful replacement page, a 404 or a 410, depending on whether an equivalent destination exists. The CMS should make that choice deliberate rather than leaving obsolete records to produce inconsistent responses.
Generate sitemaps from eligible URLs, not database rows
An XML sitemap is a declaration of preferred discoverable URLs. It should be generated from the same publication and indexation rules used by the page renderer. Including every stored record can expose drafts, suppressed pages, duplicate routes or records with incomplete content.
A robust sitemap process should:
- Include only canonical, publicly accessible and indexation-eligible URLs.
- Separate sitemap sections by content type when that aids monitoring.
- Update output when publication status, canonical rules or routes change.
- Handle sitemap limits and index files as the collection grows.
- Expose generation errors and stale data to the operations team.
Do not treat sitemap inclusion as a ranking control. It supports discovery and prioritization, but it does not compensate for weak pages or incorrect canonicalization. More implementation detail is covered in XML sitemap automation for custom CMS platforms.
Connect internal linking to the same structured data
Programmatic pages need meaningful paths through the site. Internal links can be generated from relationships already present in the data model, such as categories, compatible products, use cases, documentation topics or editorial collections.
Define link rules that favor relevance over volume. A page might link to its parent category, closely related records, supporting guides and the next useful action. Labels should describe the destination, and repeated sitewide links should not replace contextual connections.
Relationship data may be manually curated, inferred from attributes or produced with AI-assisted tooling. In all cases, the CMS should make the source and confidence of a relationship visible enough for review. AI can help propose related content, summarize structured records or identify missing fields, but production publishing still requires validation, permissions and an audit trail.
Include media in the publishing architecture
Images and downloadable assets are part of page quality, not a separate afterthought. Programmatic templates should define acceptable media dimensions, crops, formats, alternative text ownership and fallback behavior.
A media pipeline can generate responsive variants and modern formats while preserving an original asset and its licensing or attribution data. It should prevent broken references when a record changes and avoid creating dozens of unnecessary derivatives. Editorial users need to know whether alternative text is supplied by a person, generated from structured information or still required.
For implementation considerations around formats, sizing and delivery, see building an image and media pipeline for a custom CMS.
Measure quality with release and maintenance checks
Programmatic SEO requires ongoing monitoring because data, routes and business rules change. Useful checks include:
- Pages rendered with missing or repeated primary content.
- Duplicate titles, descriptions or canonical URLs.
- Indexable pages absent from sitemaps.
- Sitemap URLs returning redirects, errors or noncanonical responses.
- Published records with no internal links.
- Broken media, missing alternative text or invalid structured data.
- Unexpected growth in parameterized or filtered URLs.
These checks can run in the CMS, in a deployment pipeline or through scheduled audits. The important design choice is to route findings to an owner and distinguish blocking defects from warnings. A small, high-value collection may justify stricter manual review; a larger catalog may require automated tests with sampled editorial review.
Choose a custom implementation when control is part of the requirement
A custom CMS is most useful when the organization needs page types, data relationships and publishing controls that do not fit cleanly into a general-purpose platform. The investment is not justified by the number of generated pages alone. It is justified when ownership of routing, workflows, indexation and data quality reduces recurring operational friction or technical risk.
Laravel and PHP can provide a practical foundation for a CMS that combines structured content, server-rendered templates, role-based editorial workflows and background jobs for media or sitemap generation. The specific framework is secondary to clear contracts between data, rendering and SEO behavior. Architecture should also leave room for migrations, monitoring, permissions and future template changes.
For broader guidance on selecting and implementing custom web software, visit Allinclusive development services. If the project needs a wider search strategy alongside the platform work, the SEO services overview provides additional context.
Implementation checklist for a governed programmatic SEO system
- Define the search intent and minimum useful content for each page type.
- Model required, optional, derived and editorially controlled fields.
- Separate stored records from publishable and indexable records.
- Specify one canonical route and lifecycle behavior for every page type.
- Build templates that assemble meaningful sections rather than repeated filler.
- Generate metadata, structured data, internal links and sitemaps from validated data.
- Provide preview tools for HTML, metadata, canonicals, schema and indexation status.
- Add automated checks for duplication, missing fields, broken links and route errors.
- Define review ownership for exceptions and AI-assisted recommendations.
- Monitor the system after launch as data, URLs and business rules evolve.
Programmatic SEO becomes manageable when it is treated as a product capability: structured inputs, explicit rules, editorial oversight and observable outputs. A custom CMS can bring those concerns together, allowing teams to scale useful page production without surrendering control over quality or indexation.


