
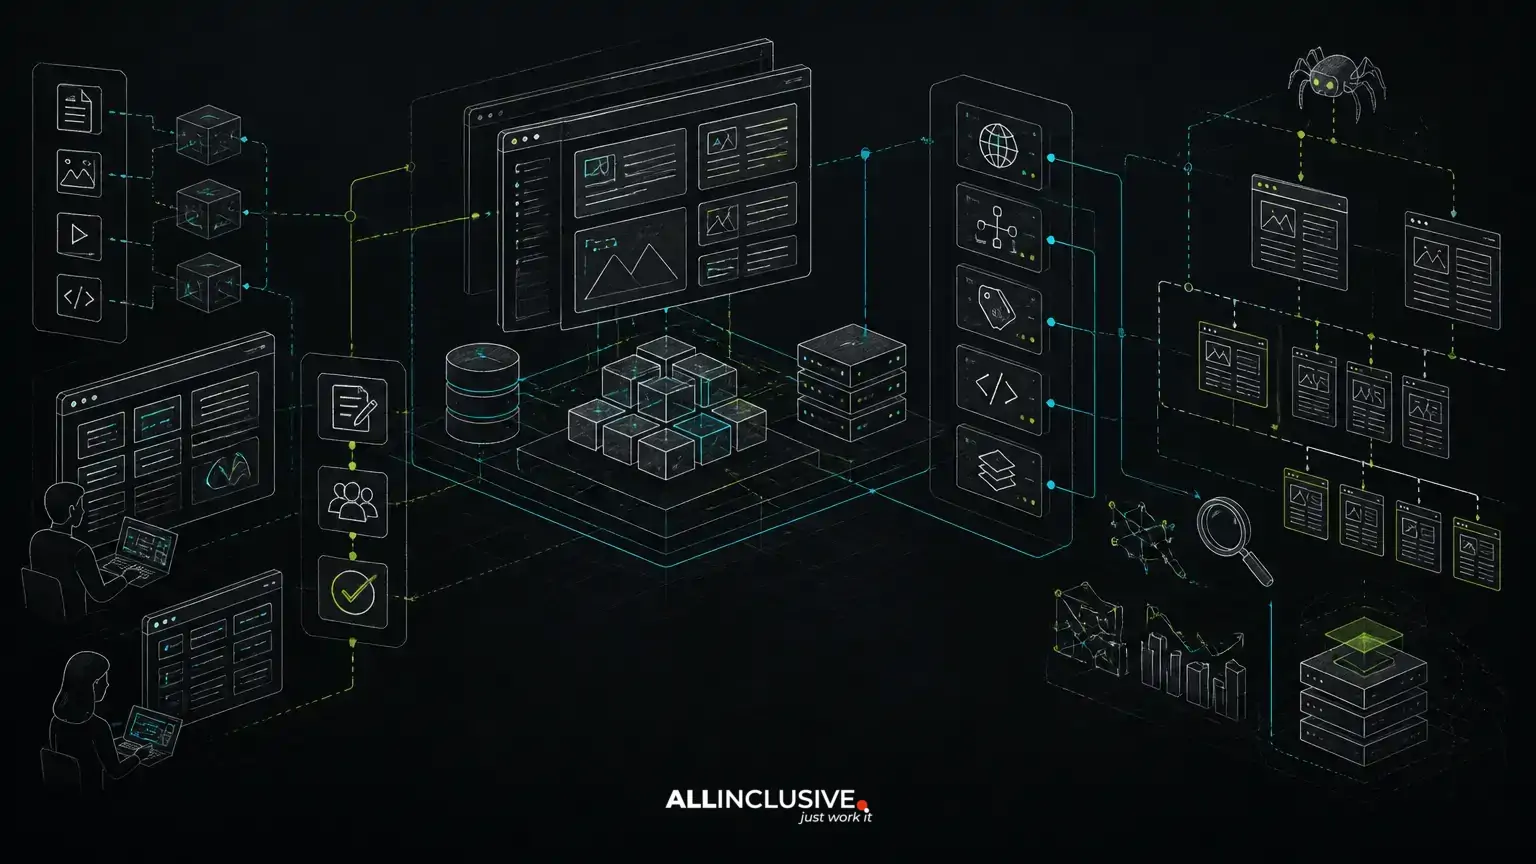
An SEO-friendly custom CMS architecture gives editors control over content while giving developers explicit control over how search engines discover, render, interpret and revisit that content. The goal is not to add a few metadata fields to an administrative screen. It is to design the CMS, application routes, rendering layer, content model and publishing workflow so that search requirements are supported by default. Teams working on seo friendly custom cms architecture may also need the implementation guidance in web development.
That means deciding early how URLs are generated, which pages can be indexed, how canonical signals are managed, how structured data is validated, how internal links are maintained and how large content sets are published safely. A custom-made CMS can support these requirements more precisely than a generic system, but only when SEO is treated as part of the software architecture.
For broader implementation context, see our custom CMS and SEO development guidance and the wider software development practice.
Start with a URL and content model that can survive growth
Search-friendly architecture begins with the relationship between content records and public URLs. A page should have a stable identity in the application, while its URL should be managed deliberately rather than assembled from uncontrolled titles or database identifiers.
A useful content model typically separates:
- the internal record identifier used by the application;
- the public slug and any approved path hierarchy;
- publication status, dates and ownership;
- redirect history when a slug changes;
- locale or market context where applicable;
- indexation and canonical preferences;
- relationships to parent, child and related content.
Slug changes should create controlled redirects instead of silently breaking old URLs. The system should also detect collisions, reserve protected paths and prevent accidental duplication between content types. A Laravel or PHP implementation can enforce these rules in domain services and validation layers rather than relying on editorial memory.
Path design should reflect information architecture, not just database structure. A product page, research article and location-specific landing page may require different route rules and different indexation defaults. Keeping those rules explicit makes future migrations, reporting and governance easier.
Make rendering behavior predictable for crawlers and users
The CMS does not determine search visibility by itself. The delivery layer determines what a crawler and a user receive at a URL. Developers should document whether each important page is server-rendered, statically generated, progressively enhanced or assembled through client-side requests.
Server-rendered HTML is often a straightforward choice for content-heavy pages because the primary text, links, headings and metadata are available in the initial response. Client-side interactivity can still be added after the core document loads. If JavaScript is required to assemble the main content, the team should test the rendered output and account for additional processing and failure modes.
Rendering decisions should cover more than the page body. The initial response should expose the intended title, description, canonical link, robots directives, structured data and meaningful internal links. Preview, draft and authenticated administrative routes should not be accidentally exposed through the same rendering path as public content.
Give editors precise metadata controls without creating chaos
A custom CMS should provide structured metadata fields, but unrestricted overrides are not automatically a quality improvement. The editorial interface should distinguish between values generated from content and values that require an intentional override.
Useful controls may include:
- SEO title and description with guidance about purpose and fallback behavior;
- social sharing title, description and image;
- canonical URL override with permission controls;
- index, noindex and follow directives;
- breadcrumb labels and navigation titles;
- structured data fields appropriate to the content type;
- preview of the rendered head and social presentation.
Fallbacks should be deterministic. For example, a missing SEO title might use a page title plus a site-level brand pattern, while a missing social image might use a content-type default. The system should record whether a value was generated or manually overridden so that editors and developers can audit unexpected output.
Dynamic metadata becomes especially important when a site contains many similar pages. The implementation should avoid producing repetitive titles and descriptions from a single rigid template. A dedicated dynamic metadata design for custom CMS platforms can help define template variables, override rules and validation before the publishing model is finalized.
Separate canonical decisions from URL generation
Canonicalization is not simply a matter of printing the current URL in a link element. The CMS needs a policy for deciding which URL represents the preferred version of a document when parameters, filters, alternate paths, syndicated content or legacy routes are involved.
Canonical rules should answer questions such as:
- Does a filtered listing have its own indexable meaning or should it point to the base listing?
- Which URL is preferred when a page is reachable through multiple content hierarchies?
- How are trailing slashes, casing and encoded characters normalized?
- What happens when a page is unpublished but its old URL remains known?
- How are alternate language or regional versions related to the canonical?
Canonical tags are useful signals, but they do not replace redirect, linking and indexation decisions. A robust architecture applies consistent normalization at routing level, generates canonical output from the same source of truth and provides an audit view for conflicting overrides.
Control indexation as a publishing and governance feature
Not every record in a CMS should become a public search result. Drafts, preview URLs, internal search results, faceted combinations, thin archive pages and incomplete programmatic records often require different treatment from primary content.
Indexation controls should therefore exist at several layers:
- Route level: private, administrative and preview routes should be inaccessible or clearly excluded from indexing.
- Content level: editors should be able to mark exceptional pages noindex when policy allows it.
- Template level: page types should have safe defaults for indexability.
- Data quality level: incomplete or duplicate records should be blocked from publication or placed in a review state.
These controls should be visible in the editorial workflow. A page that is marked noindex, lacks required relationships or has an invalid canonical should produce a clear warning rather than an unexplained change in search performance.
Generate sitemaps from publication truth
Sitemaps should be generated from the same publication and indexation rules that govern public pages. A sitemap entry should not be created merely because a record exists in a database.
The generator should consider publication status, canonical selection, noindex directives, locale, content type and update timestamps. Large sites may require separate sitemap files by content type, language or business area, with an index that remains within the relevant protocol limits. The implementation should also define how deleted, redirected and temporarily unavailable URLs are handled.
For operational reliability, sitemap generation can be synchronous for small changes or queued for larger content sets. Either way, the process needs observability: logs, validation reports and alerts for unexpected drops or spikes in URL counts. Sitemaps are not a substitute for internal linking, but they provide a useful inventory for technical auditing.
Build structured data around content types, not arbitrary text fields
Structured data is most maintainable when it is derived from a controlled content model. An article, product, event, organization or FAQ record may each have different required properties and validation rules. Developers should avoid offering a generic JSON field as the only way for editors to manage schema.
Instead, the CMS can expose content-type-specific fields, generate the stable portions of the markup and validate required relationships before publication. It should also handle absent values conservatively rather than emitting empty or misleading properties. Structured data should describe visible, supportable page content; it should not be used to make claims that the page does not substantiate.
Schema output should be tested at the template and rendered-page levels. When content models change, regression tests can verify that required properties remain present and that malformed values do not reach production.
Design internal linking as an editorial system
Internal links affect discovery, context and user navigation, so they should not depend entirely on an editor remembering every related page. A custom CMS can model relationships such as parent pages, related resources, associated products, topic tags and recommended next steps.
Useful features include link suggestions based on approved relationships, warnings for orphaned pages, validation for broken internal destinations and controls for navigation priority. Editors should be able to override automated suggestions when they have a clear reason, while the system should preserve enough information to explain why a link appears.
Automated linking needs guardrails. Blindly inserting keyword-based links can create repetitive anchors, poor reading experiences and unintended site-wide patterns. Relationship-driven recommendations are usually easier to review and maintain than unrestricted text replacement.
Treat media handling as part of page architecture
Images and other media affect usability, accessibility and delivery efficiency. The CMS should store meaningful source information, alternative text, licensing or usage metadata where relevant, focal-point data and responsive variants.
A media pipeline can generate appropriately sized derivatives, preserve the original separately and expose stable URLs for delivery. It should also prevent deleted assets from producing silent broken references across published pages. The details belong in a dedicated custom CMS image and media pipeline, but the architectural decision belongs in the initial CMS plan because content models and templates depend on it.
Use programmatic SEO with data quality gates
Programmatic SEO can extend a CMS across structured combinations of products, services, locations or use cases. It can also create large volumes of thin, repetitive or inaccurate pages if the data model and publishing controls are weak.
A responsible architecture defines:
- the source and ownership of the underlying data;
- minimum completeness requirements for each page type;
- which combinations deserve a public page;
- unique content and useful user intent for each generated route;
- rules for canonicalization, pagination and faceted navigation;
- review, rollback and retirement processes.
Generation should be separate from publication. A preview or staging state lets teams inspect representative pages before thousands of URLs become public. For a deeper treatment of templates, data and safeguards, see programmatic SEO in a custom CMS.
Build editorial workflows that protect technical quality
SEO controls are most effective when they fit the way teams actually publish. A workflow might move content through draft, editorial review, SEO review, scheduled, published and retired states. Each transition can enforce different requirements without forcing every editor to understand implementation details.
Examples of useful gates include a required canonical review for migrated pages, alt text for meaningful images, approved schema fields for structured content and confirmation that a programmatic record meets completeness rules. Role-based permissions should determine who can change routes, indexation directives and global templates.
AI-assisted tooling can help draft metadata, identify missing links or flag potentially duplicate pages, but it should operate as an assistive layer. Human review, deterministic validation and audit logs remain necessary when generated suggestions affect public content. The AI-assisted editorial workflow guide explores how to introduce these capabilities without making publication quality opaque.
Measure the CMS through technical and editorial observability
An SEO-friendly architecture needs diagnostics, not just configuration screens. The CMS and delivery platform should make it possible to inspect:
- published URLs by content type and status;
- pages with missing or duplicate metadata;
- canonical and redirect conflicts;
- orphaned or broken internal links;
- invalid structured data inputs;
- unexpected changes in sitemap inventory;
- failed media processing and stale derivatives;
- pages published without required review steps.
These checks can run during deployment, publication and scheduled audits. The goal is to detect architectural drift before it becomes a large-scale cleanup project. Clear ownership also matters: developers maintain route and rendering rules, while content and SEO teams own policy decisions within the permissions granted to them.
A planning checklist for an SEO-friendly custom CMS architecture
Before implementation begins, the team should be able to answer these questions:
- Which content types need public, indexable URLs?
- What makes each URL stable, unique and redirectable?
- How will important content and metadata be rendered in the initial response?
- Which SEO fields are generated, editable or restricted?
- What are the canonical, redirect and parameter-handling rules?
- Which records are excluded from indexing, and who can change that status?
- How are sitemaps generated from publication truth?
- Which structured data types are supported and validated?
- How are internal relationships, orphan pages and broken links managed?
- How will media variants, alt text and asset retirement work?
- What safeguards exist for programmatic page generation?
- Which workflow gates, audit logs and monitoring reports are required?
The central principle is simple: search visibility should be supported by the system’s defaults, not rescued through repeated manual fixes. When routing, rendering, content modeling, editorial review and technical validation are designed together, a custom CMS can give product and marketing teams flexibility without surrendering control over how the site is discovered and understood.


