
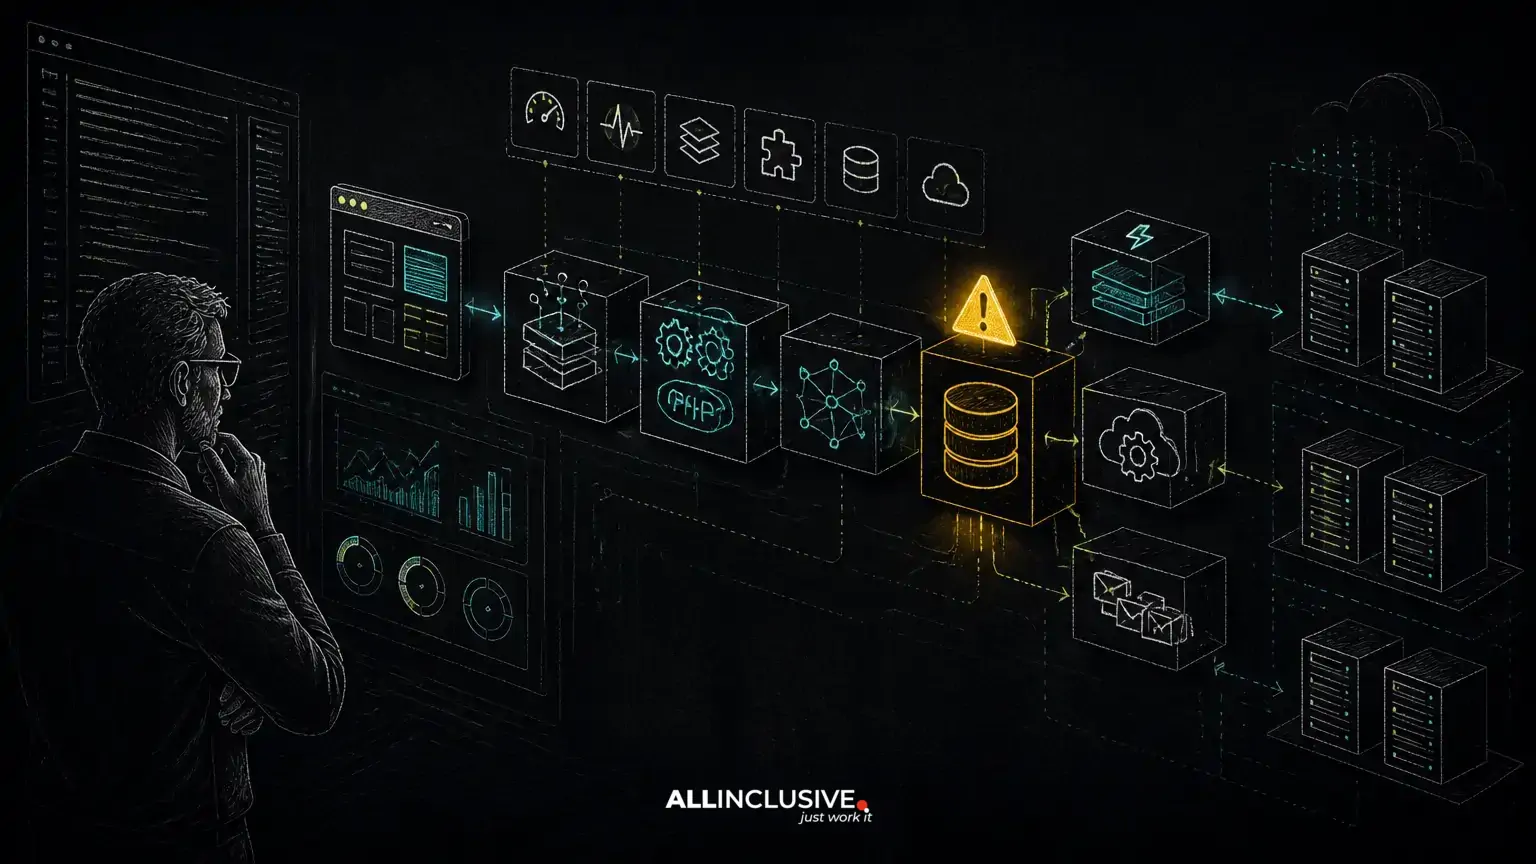
PHP performance optimization starts with evidence, not server capacity. A slow application may be limited by inefficient SQL, excessive database round trips, blocking third-party calls, expensive PHP code, poor cache behavior, resource contention or a single workflow that does far more work than expected. Adding servers can mask some symptoms, but it cannot fix a query that scans the wrong data, a request that waits on an external API or a business process that performs unnecessary work. A related decision for php performance optimization is covered in custom software development.
For custom and legacy PHP systems, the safest approach is to identify the dominant bottleneck, stabilize the application, and then make the smallest change that improves the user or business workflow. That may mean refactoring one service, correcting database access, introducing asynchronous processing, upgrading PHP, or migrating selected components to Laravel. It does not automatically mean rebuilding the application.
Start by defining the performance problem
“The site is slow” is not specific enough to guide engineering work. Begin by describing the affected operation and its business impact:
- Are page loads slow for every user or only for certain accounts, regions or data volumes?
- Does the problem affect interactive requests, background jobs, reports, exports or administrative workflows?
- Is latency consistently high, or does it appear as intermittent timeouts and error spikes?
- Did the behavior change after a release, data-growth event, infrastructure change or third-party integration update?
- Is the constraint response time, throughput, memory usage, CPU, database capacity or operational reliability?
Useful measurements should be tied to a request or job. Track response-time distributions rather than only averages, because a small number of slow requests can materially affect customers. Record database time, external-service time, application execution time, memory use, queue delay and error rates where those measurements are available. Compare normal and degraded periods against the same workflow.
Trace the request across PHP, the database and external services
Application-level timing can show that a request is slow, but it may not explain why. Break the request into meaningful spans: routing and middleware, authentication, business logic, database queries, cache operations, file or object-storage access, and third-party calls.
For example, a customer dashboard may appear to have a PHP execution problem when most of its time is spent loading several related datasets. A report endpoint may use modest CPU but consume excessive memory while building a large in-memory result. An order workflow may be fast locally but slow in production because it waits synchronously for payment, shipping or customer-data APIs.
Profiling is most useful when it is applied to a representative transaction. A synthetic homepage request can miss the expensive code path used by an account with thousands of records. Profile the workflows that users report as slow, while controlling for data size and request parameters. In production, use appropriate sampling and protect sensitive business data in collected traces.
Database behavior is often the first bottleneck to verify
PHP code can be clean and still deliver poor performance when database access is inefficient. Common causes include:
- Queries that retrieve more columns or rows than the workflow needs.
- Missing, ineffective or poorly chosen indexes.
- Repeated queries inside loops, commonly described as an N+1 query pattern.
- Sorting, joining or filtering large datasets without a suitable query plan.
- Long transactions that hold locks while application code performs unrelated work.
- Reports and exports competing with interactive requests for the same database resources.
Inspect actual query plans and execution behavior rather than assuming an index will help. An index can improve selective lookups but add write overhead and storage cost. Denormalization may speed a read-heavy workflow while increasing synchronization complexity. Pagination can reduce response size, but offset-based pagination may become expensive for deep result sets; a different approach may be appropriate depending on ordering and data requirements.
Also examine how the PHP data-access layer is used. Fetching a complete result set when a count, existence check or limited page would suffice wastes database, network and application memory. Loading related records individually can create a large number of round trips. These are often targeted refactoring opportunities that preserve business logic without requiring a framework migration.
Separate PHP execution costs from waiting time
CPU time and elapsed time are not the same. A request can have low PHP CPU usage while spending most of its lifetime waiting for a database connection, a remote API, a file operation or a lock. Conversely, inefficient transformations, template rendering, large serialization tasks or repeated permission calculations may consume application CPU without obvious database symptoms.
Look for expensive operations such as:
- Parsing or transforming large payloads repeatedly during one request.
- Rendering large collections when the user needs only a summary or first page.
- Repeated authorization, configuration or lookup work that could be computed once per request.
- Unbounded recursion or loops caused by unexpected data relationships.
- Large object graphs retained in memory longer than necessary.
- Computation that could run once during a write or scheduled job instead of on every read.
Optimization should preserve observable business behavior. A faster calculation that changes rounding, permissions, ordering or edge-case handling can create more risk than the original latency. Characterize the existing behavior with tests before changing a central domain function.
Use caching only after identifying what is safe to cache
Caching can reduce repeated work, but it is not a substitute for understanding the workload. A useful cache candidate is expensive to produce, requested repeatedly, and safe to serve within an explicitly acceptable freshness window. A user-specific balance, permission decision or inventory value may require stricter invalidation than a public reference list.
Define the cache key, ownership, expiration policy and invalidation behavior before implementation. Consider what happens when cached data is absent, stale, partially written or unavailable. A cache outage should not silently turn every request into an uncontrolled database surge.
For PHP systems, caching may exist at several levels: opcode compilation, application data, HTTP responses, database results or computed domain objects. Each layer has different invalidation and consistency implications. A cache that hides an inefficient query during testing may fail when the working set exceeds available memory or when a deployment changes the shape of the data.
For a deeper treatment of application-level choices, see Redis caching for PHP applications.
Move non-interactive work out of the request path
Users should not wait for work that does not determine the immediate response. Large exports, image processing, notification delivery, search indexing, data synchronization and some integration tasks are often better handled by a background worker.
Asynchronous processing introduces its own design requirements: durable job state, retry limits, idempotency, failure visibility, ordering rules and a clear user-facing status. Simply placing slow code in a queue does not make it reliable. A job that sends an email or creates an external record must be safe to retry without producing unintended duplicates.
When a workflow can be split, return a clear accepted or processing state and provide a way to observe completion or failure. This improves perceived responsiveness while keeping operational behavior explicit. See background jobs and queues in PHP for related architecture considerations.
Check dependencies and integrations before rewriting core code
A PHP application may be waiting on services it does not control. DNS, TLS negotiation, connection setup, rate limits, remote processing time and response size can all affect latency. A third-party endpoint that is normally fast may still create unacceptable user experience when called synchronously on every request.
Use explicit connection and response timeouts, bounded retries with backoff, and failure handling appropriate to the business operation. Do not retry non-idempotent actions blindly. Where possible, persist the intent locally and process integration work asynchronously. Measure dependency time separately so an external delay is not misdiagnosed as a PHP runtime problem.
Integration boundaries should also tolerate schema changes and partial failures. A resilient design may return a usable local response while marking downstream synchronization for later work, but that decision depends on the workflow and consistency requirements. A related decision for php performance optimization is covered in third-party integrations in PHP.
Choose between stabilize, refactor, upgrade, migrate and rebuild
Performance work in a mature application is also a modernization decision. These options are related but not interchangeable:
- Stabilize: add observability, address errors, control resource usage and remove immediate operational risks without changing the application’s overall structure.
- Refactor: improve selected code paths, queries, boundaries or tests while preserving the existing runtime and business behavior.
- Upgrade: move PHP or key dependencies to supported versions after compatibility, extension, deployment and regression concerns are assessed.
- Migrate: move a component or application to a different framework or architecture, such as Laravel, when the expected gains justify migration effort and risk.
- Rebuild: replace the application when its domain model, security posture, deployment constraints or accumulated structural problems make incremental change impractical.
Laravel can provide a clearer application structure and established conventions for routing, queues, validation, testing and data access. That does not mean every legacy PHP system should be migrated. A migration can reproduce old problems if the data model, integration behavior and business rules are copied without examination. It can also create a long period in which the team must operate and test two systems.
A Laravel migration is more defensible when the current framework or custom structure blocks delivery, supported dependency upgrades are difficult, testing is inadequate, and the business has the capacity to validate behavior incrementally. Preserve business logic deliberately: document rules, identify hidden side effects, establish characterization tests, and migrate bounded workflows rather than translating every file mechanically.
Build a performance optimization sequence that reduces risk
- Baseline the affected workflow. Capture representative timings, resource use, error behavior and data volumes.
- Trace the dominant wait. Separate PHP execution, database work, external calls, queue delay and infrastructure contention.
- Form one testable hypothesis. For example, a report is slow because it performs repeated queries for each row.
- Apply the smallest suitable change. Optimize the query, reduce payload size, add bounded caching or move work to a job before changing the entire architecture.
- Verify correctness and regression risk. Compare results, permissions, ordering, notifications and failure behavior.
- Measure under realistic load and data. A local improvement may disappear when concurrency or production-sized datasets are introduced.
- Record the decision. Document the bottleneck, change, assumptions, metrics and rollback approach.
This sequence keeps performance work connected to ownership and delivery. It also prevents a common failure mode: accumulating infrastructure changes and application rewrites without knowing which problem each change was intended to solve.
When external engineering support is useful
Specialist help is valuable when the application has limited observability, multiple interacting bottlenecks, business-critical legacy behavior or a modernization decision with significant migration risk. A useful engagement should produce more than a list of generic recommendations. It should identify the affected workflows, explain the evidence, separate quick wins from structural work, and define how improvements will be verified.
Allinclusive supports custom PHP engineering and modernization with attention to business logic, dependency risk, security and operational performance. Explore the PHP development capability, or review web development services when the performance issue spans application architecture and the broader delivery platform. Ongoing monitoring, maintenance and controlled improvements can be considered through support and maintenance.
The right PHP performance optimization strategy is rarely “add servers” or “rewrite everything.” It is a measured diagnosis of where time, memory, database capacity and operational attention are being consumed, followed by a change that improves the business workflow without discarding valuable domain knowledge.


