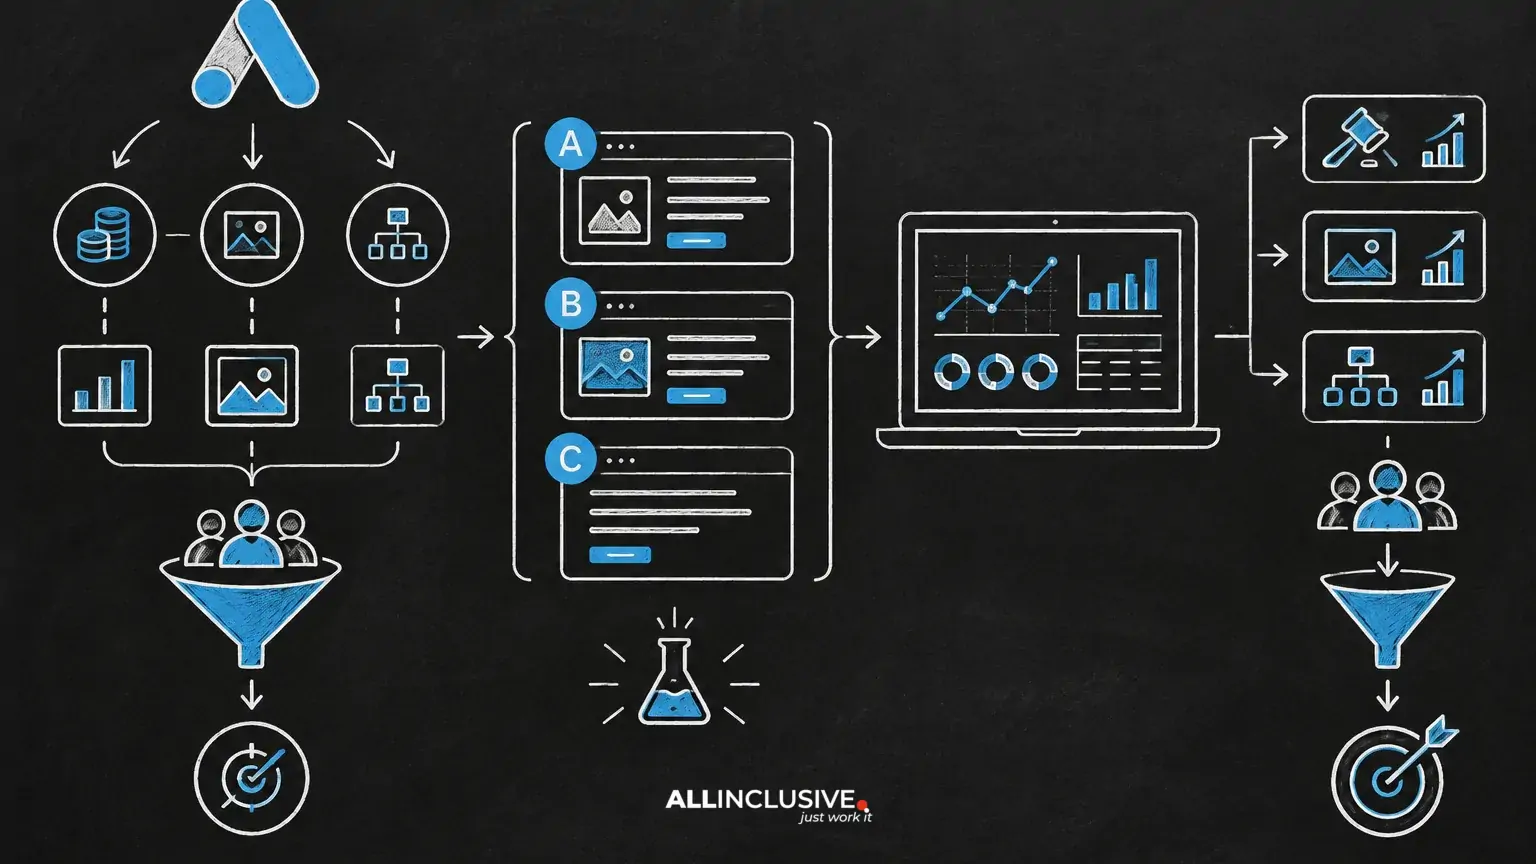
Google Ads experiments are most useful when they answer one specific business question with a controlled comparison. Rather than changing bids, creative, targeting and structure at the same time, a well-designed experiment isolates a meaningful variable, defines success before launch and gives the test enough time and data to produce an interpretable result.
This guide covers how to test bidding approaches, ad creative and campaign structure without confusing correlation with causation. The same principles apply whether you manage ecommerce, lead generation, nonprofit campaigns or a larger multi-market program.
What Google Ads experiments are designed to do
An experiment compares a defined change against a control or baseline. The change might involve a bidding approach, ad asset, landing-page experience, match-type configuration or campaign structure. The purpose is not simply to find a higher click-through rate. It is to determine whether the change improves the outcome that matters to the account.
For example, a test may ask:
- Can a different bidding approach generate more qualified conversions at an acceptable cost?
- Does a new message improve conversion rate for a high-intent search theme?
- Does separating a campaign by geography improve budget control or reporting quality?
- Does consolidating closely related campaigns give an automated bidding system stronger signals?
These are different questions and should not be combined into one test. If the bid strategy and ad message change together, an apparent improvement cannot be confidently attributed to either one.
Start with a testable hypothesis
A useful hypothesis states the proposed change, the expected mechanism and the primary metric. A weak hypothesis says, “This campaign should perform better.” A stronger version says, “Using a value-oriented message for searches containing a specific product category will increase qualified conversion rate without raising cost per qualified lead beyond the agreed threshold.”
Document the following before launching:
- Business question: What decision will the test support?
- Variable: What single factor is changing?
- Control: What remains unchanged for comparison?
- Primary metric: Which outcome determines success?
- Guardrails: What secondary measures prevent a misleading win?
- Test window: When will the test begin, end and be reviewed?
- Decision rule: What result justifies adoption, iteration or rejection?
Choose a primary metric close to the commercial outcome. For lead generation, qualified leads, pipeline value or cost per qualified lead may be more useful than raw conversion volume. For ecommerce, contribution margin or value per click may matter more than revenue alone if product economics differ.
How to test bidding approaches
Bidding tests are often difficult because auction conditions, conversion volume and budget distribution can change during the test. The safest approach is to test a bidding change where the campaign has a clear objective and enough recent performance history to make the comparison meaningful.
Define the role of the bid test
First decide whether the test is intended to improve efficiency, increase qualified volume, capture more available demand or support a value-based objective. A strategy that increases conversions may still be unsuitable if lead quality declines. Conversely, a higher cost per conversion may be acceptable when average deal value rises.
Useful bid-test questions include:
- Will a target-based approach maintain efficiency while allowing additional qualified volume?
- Will a value-oriented approach prioritize higher-value actions more effectively than a volume objective?
- Is the current target too restrictive for the available demand and budget?
- Does a manual or less automated approach provide enough control while conversion tracking is being repaired?
Keep the comparison fair
A bid test should avoid simultaneous changes to budgets, targeting, conversion definitions, landing pages and creative. If those changes are necessary, record them and treat the outcome as a broader intervention rather than a clean bidding experiment.
Review more than the platform-reported headline metric. Examine conversion quality, impression share, click volume, average cost, search-term mix and downstream outcomes where available. For lead generation, a lower reported cost per lead can mask a deterioration in qualification rate. For nonprofits, donation value, completed actions and the quality of contributed traffic may matter more than clicks alone.
Expect a transition period
Automated bidding systems may need time to adjust after a meaningful change. Avoid making frequent target edits because early volatility can make the test impossible to interpret. Establish a review cadence, but do not treat every daily fluctuation as a decision signal.
If volume is too low for a reliable comparison, the right conclusion may be that the test is inconclusive. Do not convert an inconclusive result into a permanent account change merely because one variant had a favorable short-term average.
How to test ad creative
Creative tests work best when the message change is explicit. Instead of replacing an entire ad with several unrelated ideas, test one proposition at a time: a clearer benefit, a different proof point, a stronger qualification message or a call to action aligned with the landing page.
Choose a message variable
Common creative variables include:
- Value proposition: speed, reliability, flexibility, expertise or another relevant benefit.
- Audience framing: language tailored to a role, industry or use case.
- Proof: process detail, customer evidence or a verifiable differentiator.
- Qualification: pricing context, eligibility or service boundaries that improve lead quality.
- Call to action: request a consultation, compare options, download a guide or complete another appropriate action.
Keep the landing-page promise consistent with the ad. If the ad test changes the offer and the landing page changes at the same time, you are testing the full message experience—not the ad alone. That can still be a valid test, but it needs to be labeled accurately.
Evaluate creative beyond click-through rate
Click-through rate can indicate message relevance, but it is not a sufficient success measure. A compelling claim may attract more clicks without producing more qualified actions. Review conversion rate, cost per meaningful action, lead quality, revenue or downstream engagement as appropriate.
Also check whether traffic mix changed. A new message can attract different queries or audiences, making performance differences partly a targeting effect. Search-term analysis and audience segmentation can help identify that shift.
How to test campaign structure
Structure tests should begin with an operational problem. Campaign separation may be justified when different markets, budgets, objectives, compliance requirements or reporting needs require distinct control. It is not automatically better to create more campaigns, ad groups or audience divisions.
Questions to ask before restructuring
- Does each segment need a different budget or bid objective?
- Will separation improve query control, message relevance or landing-page alignment?
- Will the split reduce conversion data available to automated optimization?
- Can the team maintain the additional complexity?
- Will reporting become more actionable, or merely more detailed?
A structure test might compare one consolidated campaign with separate campaigns for materially different regions or product lines. Another might test whether a high-value search theme deserves its own budget because it competes with lower-value traffic.
Measure both performance and manageability. A structure that produces a small efficiency improvement but creates fragile budgets, duplicated negatives and difficult maintenance may not be the better operating model.
For context on how reach can be affected by auction competitiveness and budget constraints, see our guides to Search Lost IS (Rank) and Search Lost IS (Budget). These diagnostics can help prevent a structural test from being mistaken for a demand problem.
Design the control and measurement plan
The control is the reference point against which the test is judged. It should be exposed to comparable demand wherever possible. If one variant runs during a seasonal peak and the other runs during a quieter period, the comparison is weakened.
Before launch, confirm:
- Conversion actions are defined consistently across variants.
- Tracking is working and deduplication is understood.
- Budgets are sufficient to avoid an unintended budget cap in one arm.
- Geography, language, devices and schedules are comparable unless they are part of the test.
- Brand and non-brand traffic are not being mixed without a clear reason.
- External factors such as promotions, outages or major media activity are recorded.
Use a pre-test snapshot that includes spend, impressions, clicks, conversions, conversion value, cost per outcome and relevant quality indicators. This creates an audit trail and helps distinguish a true test result from a broader account shift.
Read results without overclaiming
Do not call a test a winner because one metric moved in the desired direction for a few days. Review the full test period, compare like-for-like segments and look for consistency across the primary metric and guardrails.
A practical decision framework is:
- Adopt: The change improves the primary outcome without breaching important guardrails.
- Iterate: The signal is promising, but quality, volume or implementation needs more work.
- Reject: The change underperforms or introduces unacceptable risk.
- Extend: The result is inconclusive because volume, tracking or external conditions prevented a sound comparison.
Consider practical significance as well as statistical confidence. A small improvement may not justify implementation risk or added complexity. Conversely, a strategically important result may justify a cautious rollout even when the dataset is limited, provided the decision is documented as directional rather than conclusive.
Common experiment mistakes
Testing too many variables
Changing bids, ads, landing pages and structure simultaneously creates an intervention, not an isolated experiment. Split the work into stages or clearly define the test as a package change.
Stopping on a convenient date
Ending a test after a strong day or weak day encourages hindsight bias. Set the review criteria before launch and account for normal variation in demand.
Optimizing for the easiest metric
Clicks and platform-reported conversions are accessible, but they may not represent business value. Connect paid-search reporting to qualified outcomes wherever possible.
Ignoring budget and auction pressure
A variant may appear weaker because it is budget constrained or enters more competitive auctions. Review impression share diagnostics and auction context before drawing conclusions. Our guide to Auction Insights in Google Ads provides a framework for interpreting competitive pressure.
Failing to record decisions
Maintain an experiment log with the hypothesis, launch date, changes, anomalies, results and final decision. This prevents teams from repeating failed tests and makes future account reviews more useful.
A repeatable operating process
Build experimentation into account management rather than treating it as an occasional tactic. A simple process is to maintain a backlog of hypotheses, rank them by expected business impact and implementation effort, then run one or two controlled tests at a time.
After each test, convert the outcome into an action: roll out the change, revise the hypothesis, repair measurement or stop pursuing the idea. Revisit the account structure periodically as objectives, products, markets and conversion signals change.
For broader planning, connect your testing program to the principles in our paid search guidance and the wider paid media framework. Experiments are most valuable when they support a clear acquisition strategy—not when they generate isolated platform metrics.
Google Ads Experiments: Final Review Checklist
- Is there one clearly stated hypothesis?
- Is the primary business outcome defined before launch?
- Is the control comparable and protected from unrelated changes?
- Are conversion tracking and quality signals reliable?
- Have budgets, auction pressure and seasonality been considered?
- Is the test long enough to support a responsible decision?
- Are adoption, iteration, rejection and inconclusive outcomes defined?
- Has the result been documented for future account decisions?
Well-designed Google Ads experiments do not eliminate uncertainty. They make uncertainty manageable. By isolating variables, measuring meaningful outcomes and documenting the decision process, teams can improve paid-search performance without turning every account change into an untestable guess.