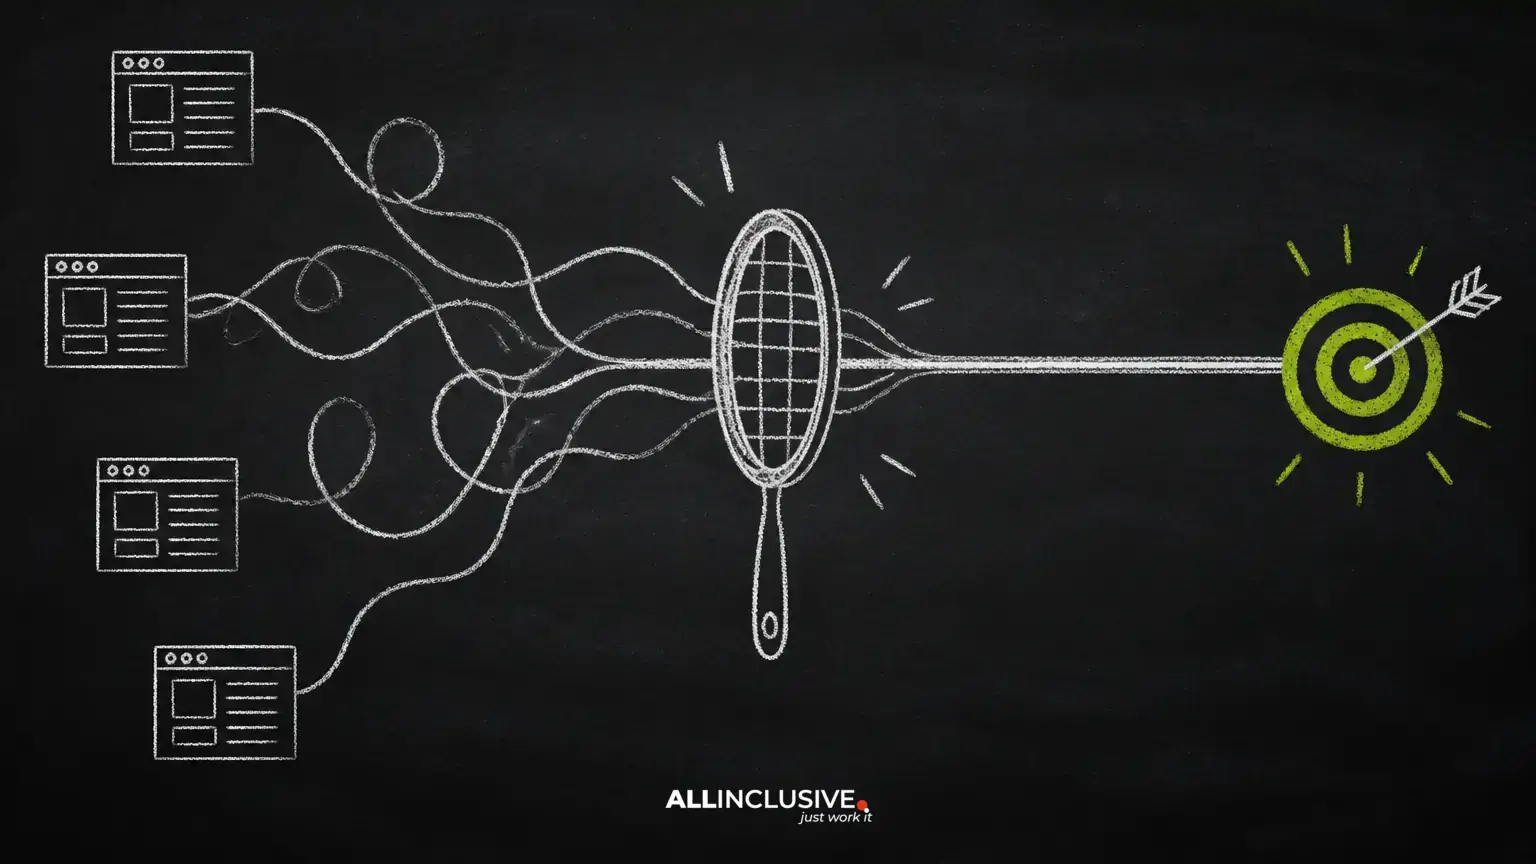
Duplicate content happens when substantially similar content is available at more than one URL, either within your site or across different sites. Some duplication is intentional and harmless, such as a printer-friendly version or a product page accessible through several navigation paths. The problem begins when search engines must decide which URL to crawl, index, rank, and show.
The practical goal is not to make every sentence on a website completely unique. It is to create one clear, preferred URL for each meaningful page and use consistent technical signals for alternatives. This guide explains how to diagnose duplicate content and select a fix without removing useful pages or blocking important crawling signals. A broader crawl review can also reveal issues covered in site crawler errors.
Why duplicate content deserves an SEO review
Search engines can often filter near-identical pages themselves. However, unmanaged duplication can make site architecture harder to interpret and can split internal links, crawl attention, and external references between several URLs. It may also cause an unexpected version of a page to appear in search results.
Common symptoms include an alternate URL being indexed, important pages remaining unindexed, inconsistent title or snippet display, and reports showing several URLs for the same content. These symptoms do not prove that duplicate content is the sole cause of a performance change. They indicate that the URL set and its signals should be investigated.
Duplicate content is also different from a search-engine penalty. A page may be filtered or replaced because another version appears more suitable, without the site receiving a manual action. Avoiding exaggerated penalty claims leads to better diagnostics and safer fixes.
Typical sources of duplicate URLs
Technical URL variations
HTTP and HTTPS, alternate hostnames, capitalization, trailing-slash conventions, and default file names can all create multiple addresses for similar resources. Choose one canonical URL format and make internal links, XML sitemaps, redirects, and structured references consistent with it.
Parameters and faceted navigation
Sorting, filtering, tracking, session, and internal-search parameters can generate many URL combinations. Some filters create useful, indexable landing pages; others merely reproduce an existing category or product page. Treat these cases differently rather than applying one rule to every parameter.
Content syndication and republishing
Publishing the same article on several domains creates duplication outside your primary site. A publisher may decide to keep the original page as the preferred version, use an appropriate cross-domain canonical where supported, or publish a substantially different version with a distinct purpose. Agreements and implementation should be reviewed before publication.
Templates and location pages
Shared navigation, footers, and product specifications are normal. The risk is creating many pages whose only change is a city, service, or keyword inserted into an otherwise identical template. A location or service page should exist when it serves a distinct audience and provides genuinely useful information, not simply because a phrase can be swapped into a title.
Start with a duplicate-content audit
- Inventory indexable URLs. Crawl the site and compare the results with XML sitemaps, analytics landing pages, internal links, and known page templates.
- Normalize URL patterns. Group equivalent URLs by host, protocol, path, case, slash convention, and query-string behavior.
- Compare content similarity. Look for exact copies, repeated main content, thin variations, and pages that share a template but serve different search intents.
- Review search visibility. Check which version is indexed and whether the selected URL matches the page you want users to find. Search Console URL inspection and indexing reports can support this review, but their data should be interpreted alongside a crawl.
- Map the preferred page. For each duplicate group, record the URL that should remain accessible, indexable, internally linked, and represented in the sitemap.
Do not treat every similar page as a duplicate automatically. Two pages may share specifications or introductory text while answering different questions. Consolidation should be based on intent, usefulness, and business purpose, not only on a similarity percentage from a tool.
Choose the right technical solution
Use a 301 redirect when the alternate page should disappear
A permanent redirect is usually appropriate when two URLs represent the same resource and the old address has no independent reason to remain accessible. Examples include a migrated URL, an obsolete slug, or a duplicate protocol and hostname. Redirect the old address directly to the preferred equivalent, update internal links, and avoid redirect chains.
Do not redirect every page to a broad category or the homepage simply to remove an audit warning. The destination should satisfy the visitor’s original expectation. If no relevant replacement exists, a carefully considered not-found or gone response may be more honest.
Use a canonical when alternatives remain accessible
A rel="canonical" link element identifies the URL you consider the representative version of substantially similar content. This can be useful for parameterized product URLs, print variants, or other accessible alternatives that do not need separate search visibility.
A canonical is a preference signal, not a substitute for sound architecture. The preferred URL should be accessible, return a successful response, contain the intended content, and be consistent with internal links and sitemaps. Avoid pointing a page at an unrelated destination or creating long chains of canonicals.
Use noindex when a page should remain accessible but not appear in search
A noindex directive can suit internal-search results, low-value filter combinations, staging-like public pages, or other URLs that users need but search engines do not need to index. Confirm that crawlers can access the page and read the directive. Blocking the URL in robots.txt can prevent crawlers from seeing the noindex instruction, so those controls should not be treated as interchangeable.
Noindex is not generally the best solution when the page is a true duplicate that should simply resolve to another URL. In that situation, a redirect or canonical may better consolidate signals.
Use robots.txt for crawl restrictions, not as a canonicalization tool
Robots.txt can control whether crawlers request URL patterns, but it does not reliably communicate which duplicate should be indexed or replace a canonical. Use it for appropriate crawl-management cases after understanding the consequences, and do not rely on it alone to select a preferred page.
Build consistent signals around the preferred URL
Technical fixes work best when the site repeatedly identifies the same version. Link to the preferred URL from navigation and body copy, include that version in XML sitemaps, use it in structured data where relevant, and make sure the page’s canonical points to itself when a self-referencing canonical is part of your implementation standard.
Check redirects at the server or application layer, preserve important query parameters only when required, and ensure alternate language or regional pages are not incorrectly canonicalized into one another. International versions can be similar while still serving distinct audiences; they require careful localization and language signals rather than blanket consolidation.
How to handle copied content on another site
First document the original publication details and compare the copied page with your own. If the copied version creates confusion or violates an agreement, contact the site operator with a clear request for removal, attribution, or correction. Keep records of the correspondence.
A self-referencing canonical can reinforce your preferred URL, but it cannot force another site to use that signal or guarantee search selection. If the matter involves substantial unauthorized use, seek appropriate legal advice and follow the relevant platform or hosting procedures. Do not assume that an external copy automatically harms the original page.
A practical maintenance checklist
- Define one standard for protocol, hostname, case, and trailing slashes.
- Keep internal links and sitemaps aligned with preferred URLs.
- Review parameter, filter, and internal-search patterns after platform changes.
- Test canonicals, redirects, and noindex directives in rendered and raw HTML where relevant.
- Recheck duplicate groups after migrations, redesigns, faceted-navigation changes, and syndication launches.
- Prioritize pages that matter to users and business goals instead of trying to eliminate every repeated template element.
For a broader technical review covering crawlability, indexing, URL architecture, and implementation priorities, see Allinclusive’s technical SEO guide. If the issue is part of a wider organic-search program, the SEO services overview provides a useful starting point for evaluating the work involved.
Conclusion
Duplicate content is best handled as a URL and information-architecture problem. Find the competing versions, decide which page deserves to remain discoverable, and select a redirect, canonical, noindex, or crawl-control approach that matches that decision. Then reinforce it with consistent links, sitemaps, and monitoring. The result is a clearer site for users and more reliable signals for search engines.